[English](README.md) | [简体中文](i18n/README.zh-CN.md)
# pi-voicekit
> **Community continuation of [`codexstar69/pi-listen`](https://github.com/codexstar69/pi-listen)** (upstream, MIT — dormant since v7.2.2 in May 2026).
> Not affiliated with the original author. Old name: `pi-listen`.
> **This fork removes every cloud backend** (0.6.0): dictation, punctuation and speech all run
> on your machine, so upstream's two-backend setup no longer applies — see [Privacy](#privacy).
**Voice in and voice out for [Pi](https://github.com/earendil-works/pi-coding-agent).**
Hold-to-talk dictation with 21 offline models and a live preview above the editor, plus speech
that reads the agent's replies aloud. Recognition, punctuation and synthesis all run in process on
[sherpa-onnx](https://github.com/k2-fsa/sherpa-onnx): there is no key, no endpoint and no
account to set up, and no audio is uploaded to a remote speech service.
> **Language scope: Chinese and English.** Recognition and punctuation are validated for Chinese,
> English and mixed Chinese–English dictation only. Every other language a model happens to cover
> is out of scope and unvalidated — see [Language scope](#language-scope).
[](https://www.npmjs.com/package/pi-voicekit)
[](https://github.com/CyFeng16/pi-voicekit/blob/main/LICENSE)
[](https://x.com/baanditeagle)
> **0.6.0 — one path, the local one.** Both cloud backends are gone from the code: no
> streaming transport, no cloud voices, nothing to authenticate. Upgrading from 0.5.x
> erases the retired fields from `settings.json` on the first start — see
> [Privacy](#privacy). Earlier releases are documented in the [changelog](CHANGELOG.md).
---
## See How It Works
Click to watch the demo video
---
## Setup (2 minutes)
### 1. Install the extension
```bash
# In a regular terminal (not inside Pi)
pi install npm:pi-voicekit
```
### 2. Pick a model
Open the panel with `/voice-settings`, go to the **Models** tab and press `↵` on the model
you want. It downloads once (43 MB for the smallest, 671 MB for the recommended Parakeet)
and becomes the active model. The language row then offers exactly the languages that model
supports.
`/voice-setup` opens the same panel — it is an alias, not a separate wizard.
Nothing here costs money or needs an account: the models are public downloads and the only
budget they take is disk space.
### 3. Check audio capture
pi-voicekit auto-detects your audio tool. No manual install needed if you already have sox or ffmpeg.
| Priority | Tool | Platforms | Install |
| -------- | --------------- | --------------------- | ------------------------------------------------------------ |
| 1 | **SoX** (`rec`) | macOS, Linux, Windows | `brew install sox` / `apt install sox` / `choco install sox` |
| 2 | **ffmpeg** | macOS, Linux, Windows | `brew install ffmpeg` / `apt install ffmpeg` |
| 3 | **arecord** | Linux only | Pre-installed (ALSA) |
> When `PULSE_SERVER` is set (SSH audio tunnel or remote PulseAudio) the order
> becomes **ffmpeg → sox → arecord** — network Pulse sources need ffmpeg.
### 4. What first start looks like
On launch pi-voicekit reports what it found and what is missing:
- **A local model.** With none selected the status line reads `MIC SETUP` and voice stays
off — a config that finished setup without a model has no working path, so the extension
sends you to `/voice-setup` instead of guessing a default. With a model, it reads `MIC LOCAL`.
- **An audio tool.** `/voice test` reports which one was detected, whether the microphone
actually produced audio, and whether the sherpa-onnx runtime loaded.
When both are in place, hold `SPACE` and dictate.
---
## Settings Panel
Everyday configuration lives in one place: `/voice-settings`. Its five tabs are General, Models,
Downloaded, Speak and Device. A few optional fields have no row of their own and are set in
`settings.json` instead — the preview's three are listed under
[Streaming preview](#streaming-preview).
### General — model, language, scope, voice
Set the local model, the dictation language, the scope (global or this project) and the voice
switch. Every row is a keyboard shortcut away — `↵` changes, `← →` switches tab.
### Models — browse, search, install
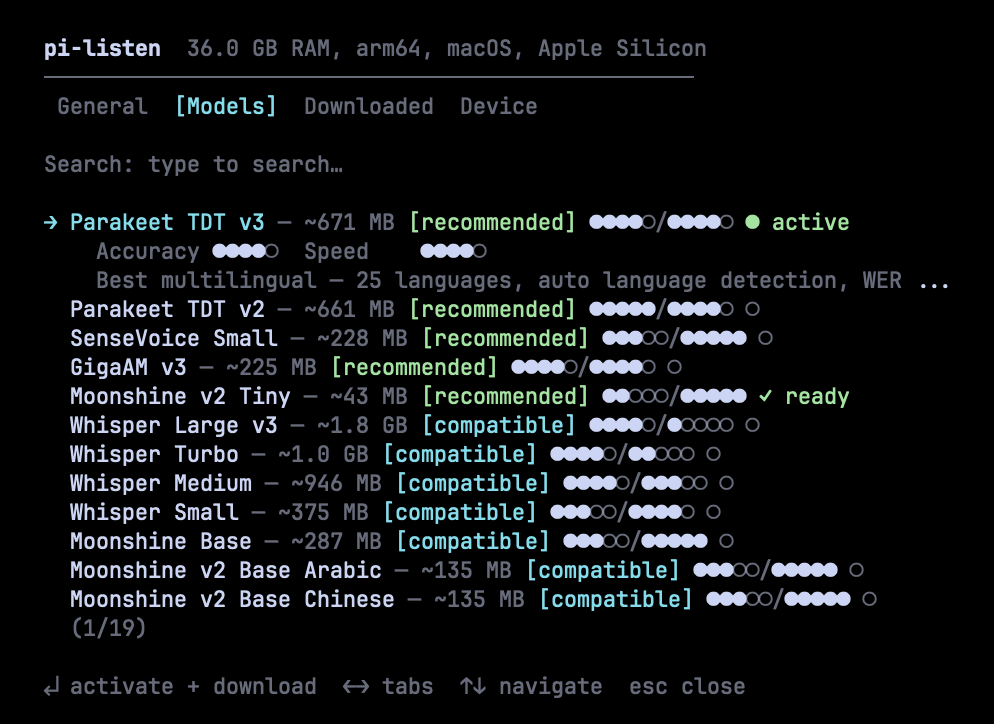 Browse 22 models from Parakeet, Whisper, Moonshine, SenseVoice, GigaAM, Paraformer, and Qwen3. Each model shows accuracy and speed ratings (●●●●○/●●●●○), fitness badges, and download status. Fuzzy search to find models fast. Press Enter to activate and download. The preview entry is the one exception: Enter downloads it when it is missing, and it can never be activated.
One of the 22 sits in its own **Preview (streaming)** group: a Chinese–English streaming Paraformer
(226 MB) that is download-only and can never become the final model. Install it and, while you
record, the words appear in a six-line panel above the editor, scrolled to the newest line.
The final transcript still comes from your offline model — the preview never writes the editor.
With the preview model not installed the preview adds nothing: no panel, no download, no prompt,
no notice. `previewEnabled` (a `settings.json` field, on by default) turns the panel off without
deleting the model.
> Screenshots were captured on a v7.0 build: the panel now has five tabs (Speak was added)
> and the catalogue has grown to 22 models.
### Downloaded — manage installed models
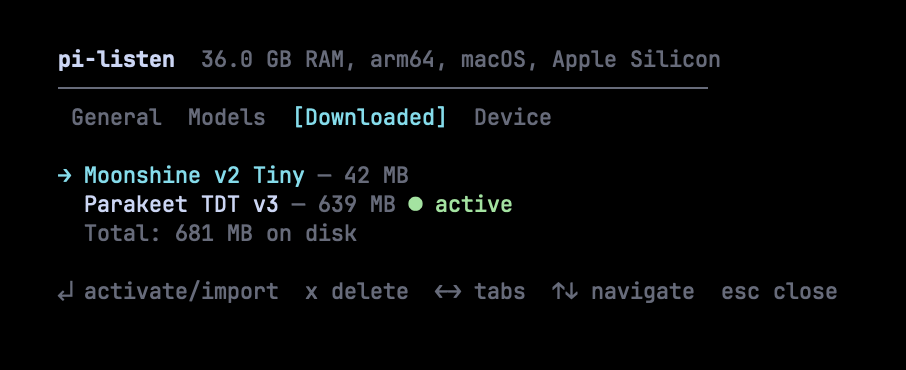 See what's installed, total disk usage, and which model is active. Press Enter to activate, `x` to delete. The preview model appears here too, marked `preview only`; Enter does not activate it. Models from [Handy](https://github.com/cjpais/handy) are auto-detected and can be imported without re-downloading.
### Speak — TTS models and voices
Twenty offline TTS models (Kitten, Kokoro, Piper) from ~13 MB, downloaded on selection;
then pick a voice and set the speed. Replies are read aloud automatically once TTS is on —
`ttsAutoSpeak` (on by default) is a `settings.json` field with no row in this tab. The panel
has a **Test** row that synthesises a sample sentence through the same pipeline.
### Device — hardware profile and dependencies
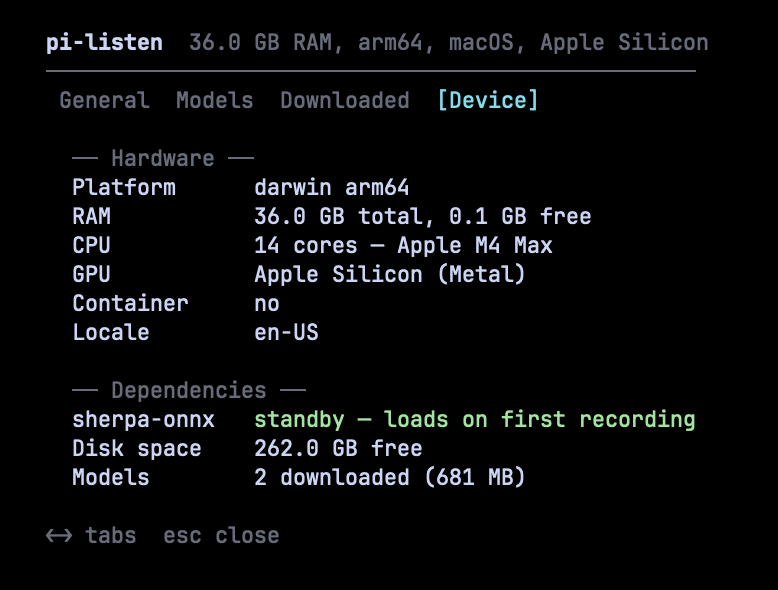 See your hardware profile (RAM, CPU, GPU), dependency status (sherpa-onnx runtime), available disk space, and total downloaded models. Model recommendations are based on this profile.
### Punctuation — offline, marks-only
Not a tab: punctuation is an automatic step between the recogniser and the editor,
on by default. When a transcript contains Chinese and is essentially unpunctuated
(fewer than one mark per 20 characters), an in-process model inserts full stops,
commas and question marks. It can only **insert** marks — every other byte of the text it
is given is preserved — and any problem leaves the text with no mark added. English is
not supported (the model measured F1 0.175 on English), and a transcript whose
punctuation is already dense enough — one mark per 20 characters or more — is left alone;
a sparser one is punctuated even if it carries a mark or two.
The model is a one-time ~285 MB download, fetched in the background from the moment a session
starts — or, on a machine where that did not happen, the first time a dictation needs it.
Either way a dictation that arrives while the download is still running gets no mark added.
Once the download has completed, verified against its digest and the engine has been
constructed — any of which can fail — later qualifying dictations are punctuated; until
then they get no mark added, and `/voice-punctuation status` reports the state. The
switch is the `punctuationEnabled` setting (a `settings.json` field, on by default — the
panel has no row for it), and `/voice-punctuation status` shows whether the step ran, why
it did not, and the state of the model.
---
## Usage
### Keybindings
| Action | Key | Notes |
| -------------------- | -------------------- | ----------------------------------------------------------------------- |
| **Record to editor** | Hold `SPACE` (≥0.7s) | Release to finalize. Capture starts when the hold reaches the threshold. |
| **Toggle recording** | `Ctrl+Shift+V` | Works in all terminals — press to start, press again to stop. |
| **Clear editor** | `Escape` × 2 | Double-tap within 500ms to clear all text. |
### How recording works
1. **Hold SPACE** — a countdown shows how long is left. Audio capture starts when the threshold is
reached, so begin speaking then: anything said during the countdown is not recorded
2. **Keep holding** — audio streams into a memory buffer, and a live preview above the editor shows
the words as the streaming model recognises them (only when the preview model is installed)
3. **Release SPACE** — recording continues for 1.5s (tail recording) to catch your last word, then finalizes
4. The active local model transcribes the buffer on a worker thread (2–10 seconds), the transcript is
cleaned and punctuated, and the text is inserted at the cursor in chunks small enough for the
editor to take whole, ready to send
### Commands
| Command | Description |
| ------------------------ | -------------------------------------------------------- |
| `/voice-settings` | Settings panel — model, language, scope, device |
| `/voice-models` | Settings panel (Models tab) |
| `/voice-setup` | Settings panel — alias of `/voice-settings` |
| `/voice-language` | Settings panel, to change the dictation language |
| `/voice-speak ` | Speak text out loud (TTS) |
| `/voice-speak-test` | Speak a sample sentence |
| `/voice-speak-toggle` | Enable / disable TTS |
| `/voice-speak-stop` | Stop in-flight TTS playback |
| `/voice-punctuation` | Offline punctuation: status, model state, last decision |
| `/voice-hold-delay` | Set hold-to-talk delay (200-3000 ms, default 700) |
| `/voice-speak-models` | Browse / install TTS voice models |
| `/voice-speak-info` | Diagnose TTS state |
| `/voice-help` | Keyboard + command reference (or press `F1`) |
| `/voice test` | Full diagnostics — audio tool, microphone, sherpa runtime |
| `/voice on` / `off` | Enable or disable voice |
| `/voice dictate` | Continuous dictation (no key hold) |
| `/voice stop` | Stop active recording or dictation |
| `/voice history` | Recent transcriptions, as written to the editor |
| `/voice info` | Settings panel |
| `/voice` | Toggle on/off |
### v7.1 keyboard
While in the settings panel:
| Key | Action |
| ------ | ----------------------------------- |
| `← →` | switch tab |
| `↑ ↓` | navigate row (skips group headings) |
| `↵` | select / activate |
| `esc` | back to main / close panel |
| `type` | filter (search) |
| `bksp` | clear last search char |
While an install widget or playback indicator is mounted (no overlay
in front):
| Key | Action |
| ----- | ------------------------------------------------------------- |
| `esc` | cancel active install (most-recent first), then stop playback |
| `F1` | open help overlay (always available) |
## Language scope
**Supported and validated: Chinese, English, and mixed Chinese–English dictation.** Every
recognition, punctuation and quality decision in this repository is made against those two
languages.
Other languages are **not supported**: the models that cover them stay in the catalogue because
they are general-purpose models, but nothing about them is validated here — no accuracy figures,
no punctuation behaviour, no device recommendation. They are on the roadmap, not in the support
matrix.
The language row offers whatever the active local model supports — a single-language model
auto-sets the language and an English-only model hides the others, so pick the model first if
the language you want is missing.
| Area | In scope | Out of scope — unvalidated |
| ----------- | --------------------------------------- | ----------------------------------------------------------------------------------------------------------- |
| Recognition | Chinese, English, mixed Chinese–English | every other language in the catalogue (Japanese, Korean, Russian, Arabic, Ukrainian, Vietnamese, Spanish, …) |
| Punctuation | Chinese today; English under evaluation | other languages |
---
## Local Models
21 offline models across 7 families, plus the streaming preview entry described above. The tables
here cover the offline ones, the only models that can produce the final transcript. Sorted by
quality — best models first. Only Chinese and English are validated; every other language listed
below is out of scope — see [Language scope](#language-scope).
### Top picks
| Model | Accuracy | Speed | Size | Languages | Notes |
| ------------------- | -------- | ----- | ------ | ---------------- | ------------------------------- |
| **Parakeet TDT v3** | ●●●●○ | ●●●●○ | 671 MB | 25 (auto-detect) | Best overall. WER 6.3%. |
| **Parakeet TDT v2** | ●●●●● | ●●●●○ | 661 MB | English | Best English. WER 6.0%. |
| **Whisper Turbo** | ●●●●○ | ●●○○○ | 1.0 GB | 57 | Broadest coverage, unvalidated. |
### Fast and lightweight
| Model | Accuracy | Speed | Size | Languages | Notes |
| --------------------- | -------- | ----- | ------ | --------------- | ------------------------------------ |
| **Moonshine v2 Tiny** | ●●○○○ | ●●●●● | 43 MB | English | 34ms latency. Raspberry Pi friendly. |
| **Moonshine Base** | ●●●○○ | ●●●●● | 287 MB | English | Handles accents well. |
| **SenseVoice Small** | ●●●○○ | ●●●●● | 228 MB | zh/en/ja/ko/yue | Best small Chinese model. |
### Specialist
| Model | Accuracy | Speed | Size | Languages | Notes |
| -------------------- | -------- | ----- | ------ | --------- | -------------------------------------- |
| **GigaAM v3** | ●●●●○ | ●●●●○ | 225 MB | Russian | 50% lower WER than Whisper on Russian. |
| **Whisper Medium** | ●●●●○ | ●●●○○ | 946 MB | 57 | Good accuracy, medium speed. |
| **Whisper Large v3** | ●●●●○ | ●○○○○ | 1.8 GB | 57 | Highest Whisper accuracy. Slow on CPU. |
Plus 8 language-specialised Moonshine v2 variants — two for Japanese, one each for Korean,
Arabic, Chinese, Ukrainian, Vietnamese and Spanish — and only the Chinese one is inside the
supported scope.
### How local models work
```
Hold SPACE → audio captured to memory buffer (plus the live preview, when installed)
↓
Release SPACE → buffer sent to sherpa-onnx inside a worker thread
↓
ONNX inference on CPU (2–10 seconds)
↓
Final transcript inserted at the cursor
```
Dictation is batch, not streaming: the final transcript appears when you finish speaking, a few
seconds later — the live preview above the editor is a separate streaming model and never becomes
the text that is inserted. Models download automatically on first use — resumable, verified after
completion, and deduplicated (no double-downloads). The streaming preview model is the exception:
it is fetched only when you press `↵` on its row in the Models tab, never on first use. The settings
panel shows real-time download progress with speed and ETA.
Models from [Handy](https://github.com/cjpais/handy) (`~/Library/Application Support/com.pais.handy/models/`) are auto-detected and can be imported via symlink (zero disk duplication).
---
## Performance
Measured on the maintainer's machine, local CPU, no network, over 70 published utterances
(28 Chinese, 28 English, 14 mixed Chinese–English). RTF is processing time divided by audio
duration — lower is better, and below 1.0 is faster than real time.
| Recogniser | Chinese RTF | English RTF | Mixed RTF | Characters per second |
| -------------------- | ----------- | ----------- | --------- | --------------------- |
| **paraformer-zh** | 0.014 | 0.013 | 0.016 | 247–983 |
| **sensevoice-small** | 0.028 | 0.029 | 0.040 | 134–451 |
| **whisper-turbo** | 0.372 | 0.369 | 0.395 | 7–27 |
End to end, the punctuation step adds almost nothing when it runs: on 27–32 character
inputs the model call measures p50 2.9 ms / p95 3.1 ms after a one-time 544 ms load,
all on CPU (see docs/BENCHMARKS.md). `whisper-turbo` is the slowest of the three by an
order of magnitude and the least accurate on this corpus — measured for comparison, not
recommended for CPU-only use.
Protocol, all result tables and the honest limits live in
[docs/BENCHMARKS.md](docs/BENCHMARKS.md) — GitHub only, because npm ships the extension and
this README.
---
## Features
| Feature | Description |
| -------------------------------- | ---------------------------------------------------------------------------------------- |
| **Local-only** | One path: in-process recognition and speech. No endpoint, no key, no account — see [Privacy](#privacy) |
| **22 local models** | 21 offline recognisers plus one streaming preview model — Parakeet, Whisper, Moonshine, SenseVoice, GigaAM, Paraformer, Qwen3 — with accuracy/speed ratings |
| **Live streaming preview** | Words appear above the editor while you record, scrolled to the newest line. The preview model is optional (226 MB), download-only, silent when absent, and never produces the final transcript |
| **Offline speech** | 20 local TTS models (Kitten, Kokoro, Piper) read the agent's replies through the system player |
| **Unified settings panel** | One overlay panel for everyday configuration — `/voice-settings`. Optional fields without a row live in `settings.json` — the preview's three are listed under [Streaming preview](#streaming-preview) |
| **Device-aware recommendations** | Scores models against your hardware. Only best-in-class models get [recommended]. |
| **Enterprise download pipeline** | Pre-checks (disk, network, permissions), live progress with speed/ETA, post-verification |
| **Handy integration** | Auto-detects models from Handy app, imports via symlink |
| **Audio fallback chain** | Tries sox → ffmpeg → arecord in order — ffmpeg first when `PULSE_SERVER` is set |
| **Hold threshold** | 200–3000 ms, default 700 ms (`/voice-hold-delay`). Capture starts at the threshold, not on the press |
| **Tail recording** | Keeps recording 1.5s after release so your last word isn't clipped |
| **Offline punctuation** | Chinese dictations that come back unpunctuated get full stops, commas and question marks from an in-process model — marks only, no wording changes, fail-open, English not supported. Both engines stay resident (~300 MB each) and the model is fetched once — see [Engine residency](docs/BENCHMARKS.md#engine-residency) |
| **Chinese + English** | The supported and validated scope, mixed Chinese–English included. Every other language in the catalogue is unvalidated — see [Language scope](#language-scope). |
| **Continuous dictation** | `/voice dictate` for long-form input without holding keys |
| **Typing cooldown** | Space holds within 400ms of typing are ignored |
| **Sound feedback** | macOS system sounds for start, stop, and error events |
| **Cross-platform** | macOS, Windows, Linux — Kitty protocol + non-Kitty fallback |
---
## Architecture
```
# core
extensions/voice.ts Main extension — state machine, recording, UI, command surface
extensions/voice/config.ts Config loading, saving, migration
extensions/voice/onboarding.ts Model and language pickers, first-run flow
extensions/voice/audio-tool.ts Capture tool detection (sox / ffmpeg / arecord)
extensions/voice/hold-to-talk.ts Hold detection, Kitty and non-Kitty terminals
extensions/voice/release-controller.ts Recording lifecycle, release handling
# speech-to-text
extensions/voice/local.ts Model catalog (22 models), in-process transcription
extensions/voice/sherpa-engine.ts sherpa-onnx bindings — recognizer lifecycle, inference
extensions/voice/sherpa-loader.ts Lazy native module loading
extensions/voice/model-download.ts Download manager — resume, progress, verification, Handy import
extensions/voice/device.ts Device profiling — RAM, GPU, CPU, container detection
extensions/voice/transcript-cleanup.ts Filler removal and spoken-numeral restoration
extensions/voice/transcript-join.ts Segment stitching — CJK-aware, no space inside a sentence
# live preview and workers
extensions/voice/preview-entrypoint.ts One preview session and one final pass per recording
extensions/voice/preview-session.ts Preview session — events, text, degradation, display lifetime
extensions/voice/preview-stream.ts Streaming segmentation — endpoint and 60 s segment cap
extensions/voice/preview-worker-client.ts Preview worker client — claims, partials, flushes, retirement
extensions/voice/local-preview-worker.ts Preview worker entry — streaming recogniser off the main thread
extensions/voice/final-pass-client.ts Final-pass worker client — timeouts, reuse, invalidation
extensions/voice/final-pass-worker.ts Final-pass worker entry — offline recogniser off the main thread
extensions/voice/transcript-composer.ts Committed prefix plus the mutable partial tail
extensions/voice/preview-panel.ts Live draft widget — six rows, tail visible, no header
extensions/voice/editor-sink.ts Cursor insertion in chunks the editor takes whole
# offline punctuation
extensions/voice/punctuation.ts Offline punctuation — marks-only splice, fail-open step
extensions/voice/punctuation-model.ts Punctuation model — catalogue, digest verification, download
# text-to-speech
extensions/voice/speak.ts Speak entry point, auto-speak wiring
extensions/voice/tts-engine.ts sherpa-onnx TTS synthesis
extensions/voice/tts-local-models.ts Local TTS catalog — 20 models (Kitten, Kokoro, Piper)
extensions/voice/tts-playback.ts Playback, buffering, player detection
extensions/voice/tts-text-filter.ts Code-block stripping, sentence prep
extensions/voice/tts-onboarding.ts TTS onboarding flow
extensions/voice/tts-onboarding-overlay.ts TTS onboarding overlay
extensions/voice/tts-install-progress.ts Model install progress widget
extensions/voice/tts-playback-indicator.ts Speaking indicator widget
# settings and UI
extensions/voice/settings-panel.ts Settings panel — overlay, 5 tabs
extensions/voice/ui-picker.ts Generic list picker
extensions/voice/ui-help-overlay.ts Keyboard and command reference
extensions/voice/ui-aura.ts Visual primitives (Liquid Braille, Aurora)
extensions/voice/ui-widget-base.ts Widget registry and base class
extensions/voice/ui-render-ticker.ts Shared render ticker
extensions/voice/ui-icons.ts Glyph and icon set
extensions/voice/ui-width.ts CJK-aware visual width helpers
extensions/voice/ui-locale-labels.ts Native language and voice labels
# benchmarks (repository only — never published)
bench/manifest.jsonl Benchmark slices: dataset, split, license, selection rule
bench/fetch.py Deterministic fetcher — writes bench/data/ (gitignored)
# types
extensions/voice/sherpa-onnx-node.d.ts Type declarations for the optional native module
```
---
## Configuration
Settings stored in Pi's settings files under the `voice` key:
| Scope | Path |
| ------- | ----------------------------- |
| Global | `~/.pi/agent/settings.json` |
| Project | `/.pi/settings.json` |
Both paths follow Pi: the global one sits in Pi's agent directory, so a build run with
`PI_CODING_AGENT_DIR` set uses that directory instead of `~/.pi/agent`; the project one uses
Pi's config-directory name rather than a literal `.pi`. Downloaded models are separate and always
live under `~/.pi/models`.
```json
{
"voice": {
"version": 6,
"enabled": true,
"language": "zh",
"localModel": "parakeet-v3",
"scope": "global",
"onboarding": { "completed": true, "schemaVersion": 6 }
}
}
```
A file carried over from 0.5.x may still hold the retired speech-backend fields; the first
start erases them and says so — see [Privacy](#privacy).
Hold-to-talk delay defaults to **700 ms** (`/voice-hold-delay` accepts 200–3000 ms).
### Streaming preview
Three ordinary optional fields: an explicit project value wins, then the global one, then the
default. All three are `settings.json` fields — the panel has no rows for them.
| Setting | Default | Notes |
| --------------------- | -------------------------------------- | ---------------------------------------------------------------------------------------------- |
| `previewEnabled` | `true` | Mount the live preview while recording. `false` also keeps the preview worker from starting. |
| `localPreviewModel` | `streaming-paraformer-bilingual-zh-en` | The streaming catalogue entry. It is never usable as the final model. |
| `maxRecordingSeconds` | `120` | Budget for one recording, in seconds — a positive finite number. |
The recording budget and the preview's 60 s segment cap are separate limits: the cap ends a
recognition segment early, it does not stop the recording. The preview model lives in
`~/.pi/models/streaming-paraformer-bilingual-zh-en/` and appears in the Downloaded tab like any
other download, marked `preview only`; pressing Enter does not activate it.
### Punctuation
Punctuation is automatic and on by default. When a dictation finishes, the transcript
is cleaned first — see the cleanup switches in the table below — then punctuated locally
if the text contains Chinese and its punctuation density is below one mark per 20
characters; the step only inserts marks and changes nothing else. The model runs in
process, and the one-time download of the model itself is the only traffic it causes.
English is not supported in this version, and English text is skipped by the same rule. A
transcript the rule declines gets no mark added, and neither does any transcript whose
punctuation fails at any point.
Both engines stay resident for the session: the recogniser as before, and the punctuation engine
built when a session starts, so no dictation waits for it (measured 0.2 ms for the call, engine
usable within 100 ms, 50-544 ms to build). On a machine that has never fetched the model, that
first session fetches it: 285 MB on disk, and roughly 300 MB of memory per engine on the reference
machine — 292 MB for punctuation, 316 MB for the `paraformer-zh` recogniser. See
[Engine residency](docs/BENCHMARKS.md#engine-residency) for the numbers.
| Setting | Scope | Default | Notes |
| ----------------------------- | ------------------ | ------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `punctuationEnabled` | global and project | `true` | Runs the offline punctuation step on qualifying transcripts. |
| `fillerRemovalEnabled` | global and project | `true` | Removes the filler particles `呃` and `嗯` from a finished transcript. |
| `numeralNormalizationEnabled` | global and project | `true` | Restores digits in spoken identifiers (`k 八 s` → `k8s`, `bf 十六` → `bf16`) and in a bare multi-point version (`零点九九点一` → `0.99.1`). |
| `punctuationNoticeShown` | global only | `false` | Machine-local bookkeeping for the one-time upgrade notice. |
All three switches resolve the same way. A machine-wide `false` is final: no project
block can turn the step back on, even one that saved `true` before the global value was
set to `false`. Below that, an explicit project value wins — a repository that saved
`false` keeps the step off when the global value later turns on — then the global value,
then the default. An omitted value in a project block inherits the global one rather than
the default. The cleanup runs before punctuation and on its own switches, so turning
punctuation off still leaves a cleaned transcript.
The first project-scope save writes the values the config resolved to — including
inherited ones — into the repository's `.pi/settings.json`, so all three keys become
concrete booleans there. That pins the project value; it does not exempt the repository
from a later machine-wide `false`, which still applies everywhere.
`/voice-punctuation status` prints the punctuation switch state, whether the model is
downloaded and digest-verified, and what the step decided on the last dictation of the
session. The model lives in `~/.pi/models/punct-ct-transformer-zh-en/`, appears in the
Downloaded tab like any other download, and selecting that row does not make it a
recogniser. The step writes one metadata-only `voice-punctuation` entry per dictation — no
transcript text — so a decision is fact; under `PI_VOICE_DEBUG` it also logs one line per
dictation with the character count, marks before and after, the gate, the reason when it
did not run, and the elapsed time. The removed `postProcess*` keys from older releases
are ignored when loading — never migrated, and left in place when the settings file is
saved.
---
## Privacy
**No audio is uploaded to a remote speech service.** Recording, recognition, punctuation
and speech synthesis all run inside the Pi process — sherpa-onnx is loaded natively and
works on buffers in memory. There is no endpoint to configure, no key to paste, no account
to create.
That is the guarantee the code keeps, and it is narrower than "nothing ever leaves the
machine". One configuration this README supports sends data off it, and it is your own
configuration rather than something the extension does by itself.
**System audio routing.** Playback hands the synthesised WAV to the system player, and that
process inherits your environment. Point PulseAudio at another host (`PULSE_SERVER`, an SSH
audio tunnel, a remote desktop session) and the player sends the speech there — the [audio
tool](#setup-2-minutes) honours the same variable, so a remote microphone means your voice
crosses that link before this extension ever sees it.
That route is not a speech service this extension chose. If you need the audio kept on this
machine, local playback is only half of it: capture honours the same variable, so both ends —
the player and the microphone — have to stay local.
Everything you send to the agent — typed, or dictated and then submitted — is text, and it
goes to whatever model Pi is configured with. That is not an exception to the claim above:
the claim is about audio, and sending a message is the path every request takes.
### What the gate checks
`tests/no-cloud-egress.test.ts` is the enforceable half of that claim. It parses every
module under `extensions/` and fails when one imports the removed WebSocket transport,
names a retired vendor identifier or host, or calls `fetch` outside the two
model-download modules (`model-download.ts`, `tts-local-models.ts`).
That is narrower than "this software can never open a socket", and it is worth saying so
plainly: the gate binds the transport and the vendor this repository deleted, and it keeps
ordinary code from growing a new call site. A future module could still build its own
network client — which is why this is a test you can read, not a promise in prose.
### The one outbound step this extension takes
Model files are downloaded from HuggingFace or GitHub releases: the speech models you pick, the
TTS models you pick, the ~285 MB punctuation model on a machine that needs it, and the optional
streaming preview model when you press `↵` on its row — never before. Downloads are resumable and
checked when they finish: the speech model files must all be present at their expected sizes, and
the punctuation model is verified file by file against the SHA-256 digests recorded in this
repository. After a model is on disk, dictation and speech work with the network down.
### What stays on the machine
- A dictation is held in a memory buffer and dropped after the transcript is written; no
recording is stored. (`/voice test` does write a one-second sample to the temp directory
to prove the microphone works — it is deleted as soon as its size is read.)
- Speech playback writes the synthesised audio to a temp WAV with mode `0600` and hands it
to the local player (`afplay` on macOS, `paplay`/`aplay` on Linux, PowerShell's
`SoundPlayer` on Windows), then deletes it. The player is local but it is a separate
process that inherits your environment, which is why [system audio
routing](#privacy) is the one exception above instead of something this
extension can promise about.
- `/voice history` keeps this session's transcripts in memory only.
- `PI_VOICE_DEBUG=1` appends diagnostics — including a 100-character transcript preview —
to `$TMPDIR/pi-voice-debug.log`. It is off unless you set it.
- No telemetry, analytics or crash reporting is transmitted: there is no crash reporter and no
remote logging.
### Upgrading from 0.5.x
0.6.0 removed the cloud backends, so the first start erases a stored provider API key and a
`localEndpoint` from `settings.json` and tells you it did — the field names are listed in
[SECURITY.md](SECURITY.md). The rest of the file is left exactly as it was, byte for byte,
including formatting `JSON.parse`/`JSON.stringify` would not preserve. An API key exported from
a shell profile or `~/.env.secrets` is no longer read at all; the extension does not edit those
files, so delete the line yourself.
See [SECURITY.md](SECURITY.md) for vulnerability reporting.
---
## Troubleshooting
Run `/voice test` inside Pi for full diagnostics.
| Problem | Solution |
| ------------------------------------------------ | --------------------------------------------------------------------------------------------------------------- |
| No microphone? "No audio capture tool found" | `brew install sox` or `brew install ffmpeg` |
| Remote microphone records silence | Audio over PulseAudio/SSH — install ffmpeg on the Pi side (capture then prefers ffmpeg) |
| Space doesn't activate voice | Run `/voice-settings` — voice may be disabled, or no model is selected |
| Nothing transcribes | `/voice-settings` → Device tab for sherpa-onnx status; `/voice test` names the failure |
| Download failed | Partial downloads auto-resume on retry. Check disk space in Device tab. |
| Unsupported platform (32-bit ARM, Windows on ARM64, musl) | The native runtime has no build for it; the message names the constraint. Use a glibc x64/arm64 system or container, or Windows on x64 |
| `dyld: Library not loaded: libsimdjson` on macOS | Homebrew Node ABI mismatch — run `brew reinstall node` or switch to version-managed Node (`mise`, `fnm`, `nvm`) |
More in [docs/troubleshooting.md](docs/troubleshooting.md).
---
## License
[MIT](LICENSE) — original by [@baanditeagle](https://x.com/baanditeagle), maintained by [CyFeng16](https://github.com/CyFeng16)
---
Continuation of pi-listen by @baanditeagle, maintained by CyFeng16
Website · 𝕏 Twitter · GitHub · npm · Report a Bug · Pi CLI