# peepshow-sink-gcs
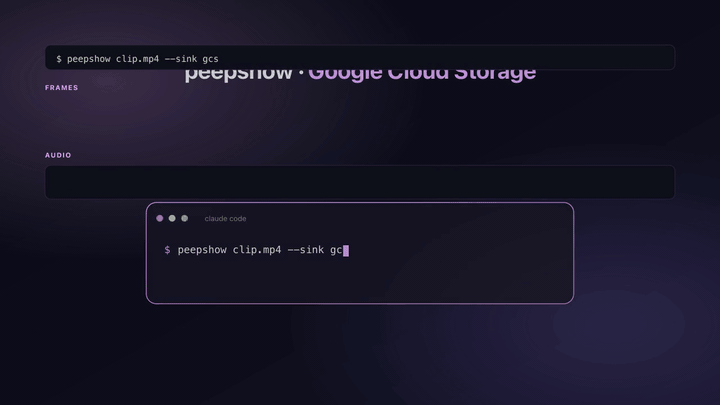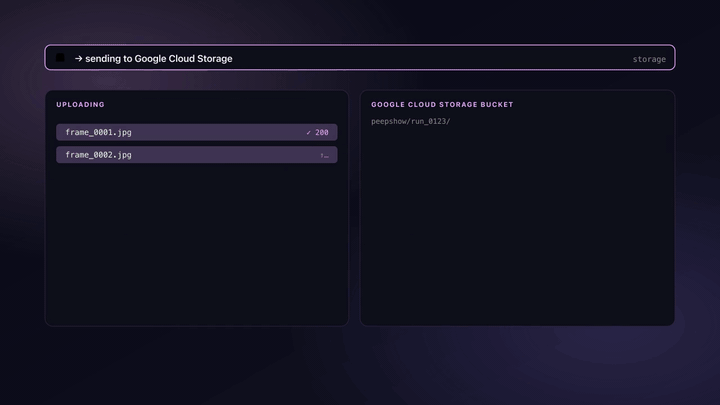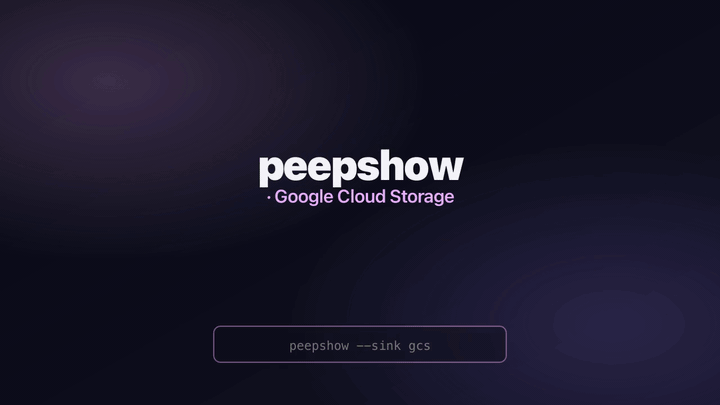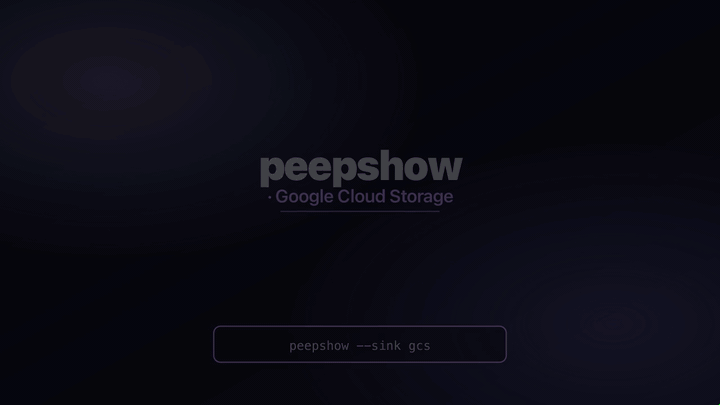
Uploads every frame plus a `manifest.json` to a Google Cloud Storage bucket using the native `@google-cloud/storage` SDK. Authenticates via Application Default Credentials — so workload identity, `gcloud auth application-default login`, or an explicit service-account JSON all work without code changes.
> If you want a provider-neutral S3-compatible upload, use [`peepshow-sink-s3`](./s3.md) with `S3_ENDPOINT=https://storage.googleapis.com`. Use this sink when you need native GCS features (uniform bucket-level access, workload identity federation, HMAC-less auth).
## Install
```bash
npm install @google-cloud/storage
```
## Config
| Env var | Required | Default | Purpose |
| :------ | :------- | :------ | :------ |
| `GCS_BUCKET` | yes | — | target bucket name |
| `GCS_PREFIX` | no | `peepshow/` | object key prefix for every upload |
| `GCS_PROJECT_ID` | no | ADC default | GCP project. SDK also reads `GOOGLE_CLOUD_PROJECT` |
| `GCS_KEY_FILE` | no | ADC default | path to a service-account JSON key |
## Auth cheatsheet
| Scenario | Setup |
| :------- | :---- |
| Local dev | `gcloud auth application-default login` — no env vars needed |
| CI runner / GKE / Cloud Run | Workload Identity — no env vars needed |
| Explicit SA key | `export GCS_KEY_FILE=/path/to/sa.json` (or set `GOOGLE_APPLICATION_CREDENTIALS`) |
## Use
```bash
export GCS_BUCKET=peepshow-archive
peepshow sinks add gcs
peepshow ./video.mp4
```
## Layout in bucket
```
--/
frame_0001.jpg
frame_0002.jpg
...
manifest.json
```
`manifest.json` bundles the full peepshow extraction payload — `video`, `extraction`, `frames`, `strategy`, `outputDir` — so a downstream job can reconstruct context from the bucket alone.
## Caveats
- Frames are uploaded sequentially (one object at a time) for simplicity; large timelines can be throttled by `GCS_MAX_UPLOADS` in a future revision.
- `Content-Type` is inferred from extension: `.jpg`/`.jpeg` → `image/jpeg`, `.png` → `image/png`, `.webp` → `image/webp`, else `application/octet-stream`.
- No server-side lifecycle config — set object lifecycle rules at the bucket level if you need automatic expiry.
- Requires `storage.objects.create` on the bucket; the default `roles/storage.objectCreator` is sufficient.
## Use with an LLM agent
Every peepshow sink is a zero-config extension point for any LLM CLI —
Claude Code, Cursor, Windsurf, Codex, Gemini, or any agent that can shell
out. The LLM doesn't need a plugin; it just needs `peepshow` on `PATH` and
the sink's env vars in the shell it runs under.
### 1. Set the environment
Add the sink's required env vars to your shell rc (`~/.zshrc`,
`~/.bashrc`, PowerShell profile) or a project-local `.env` that your
agent tooling loads. Example:
```sh
export GCS_BUCKET="your-value"
```
### 2. Register as an auto-sink
Auto-sinks fire on every `peepshow` run without per-invocation flags,
so the LLM doesn't have to remember a pipeline — the routing is
declarative:
```sh
peepshow sinks add gcs
# Optional: only fire for matching inputs
peepshow sinks add gcs --when extension=mp4,mov
peepshow sinks add gcs --when retention=long
```
See [`peepshow sinks`](../../docs/PLUGINS.md) for the full matching
vocabulary.
### 3. An LLM session, end-to-end
> **You**: drop a `clip.mov` into Claude Code (or ask
> "what's in ~/bugs/crash.mov?")
>
> **Claude Code**: the `UserPromptSubmit` hook detects the video and
> auto-invokes `/peepshow:slides ~/bugs/crash.mov`. peepshow extracts
> frames + audio, transcribes locally if `whisper.cpp` is on `PATH`,
> then forwards the run to the `Google Cloud Storage` sink.
>
> **`Google Cloud Storage`**: uploads every frame plus a `manifest.json` to a Google Cloud Storage bucket under a timestamped prefix.
>
> **Claude Code**: reads the frames back as images, combines them with
> the audio transcript, and writes a summary that references the
> downstream record.
### 4. What the sink sees
The sink receives the complete `--emit json` payload on stdin — not just
the frame paths. That includes:
- `video` — codec, duration, resolution, container tags (director / studio
/ title etc).
- `frames[]` — every extracted frame path + byte size.
- `audio` — `path`, `durationSeconds`, codec, loudness peak, silence
ratio.
- `audio.transcript` — `segments[]` with timestamps, full `text`,
language — populated when transcription is enabled (v0.4.0+).
- `extraction` — strategy, thresholds, ffmpeg path used.
> **Transcript handling**: the full transcript JSON is saved next to the frames in the per-run manifest.