# next-leak
[](https://www.npmjs.com/package/next-leak)
[](https://github.com/xabierlameiro/next-leak/actions/workflows/ci.yml)
[](https://nodejs.org)
[](./LICENSE)
> Find out whether your Next.js app actually leaks memory — how much, on which route, and whose fault it is.
 ```
$ npx next-leak . --quick
✖ /api/heap leak (+4.70 MB/1000 req)
heap 28.7 → 40.3 → 59.0 → 75.8 → 75.9 → 101.2 → 101.2 → 139.0 → 139.0 MB
↳ grown [object] Array 112.5 MB — TimeoutsManager#object[.resources]
<- system / Context#object[.timeoutsManager] <- destroy#closure[.context]
<- ResourceManager#object[.properties] <- IntervalsManager#object[.map]
✔ / stable (+0.02 MB/1000 req) heap 40.9 → 35.3 → 35.3 → 35.4 MB
✔ /convenio stable (+0.02 MB/1000 req) heap 36.3 → 37.0 → 37.1 → 37.1 MB
```
That first line is a real run against the reproduction for
[vercel/next.js#95094](https://github.com/vercel/next.js/issues/95094): the
sandbox's `TimeoutsManager` never released timeout ids from middleware.
next-leak found the growth, the retaining object and the chain that holds it —
without being told what to look for. Next.js 16.3.0 has since fixed it.
**Verified against real Next.js issues**, not synthetic fixtures. Issue states
checked 2026-09-19:
| Issue | What it is | Measured | State today |
|---|---|---|---|
| [#97938](https://github.com/vercel/next.js/issues/97938) | `use cache` / `cacheComponents`: `AbortSignal.any` composites never released (canonical issue since Sep 9; #97776 and #97464 are duplicates) | +705 KB per request on 16.3.3, flat on 16.2.6 | fixed in **16.3.5** (Sep 11) by [#98448](https://github.com/vercel/next.js/pull/98448), the backport of [#97476](https://github.com/vercel/next.js/pull/97476); re-measured Sep 14: +709 KB per request on 16.3.4, flat on 16.3.5 |
| [#97776](https://github.com/vercel/next.js/issues/97776) | `use cache`: the same composites, reported from production | the #97938 run above | closed Sep 9 as a duplicate of #97938; fixed in 16.3.5 |
| [#96533](https://github.com/vercel/next.js/issues/96533) | ISR revalidation holds RSC buffers between collections | 4–5 MB of `arrayBuffers` held vs 0.32 MB retained | **open** |
| [#97464](https://github.com/vercel/next.js/issues/97464) | Static-gen worker retains per prerendered page | OOM after 1617 and 1525 of 2504 pages on 16.3.3; 16.2.12 finishes at 0.05 MB/page | closed Aug 31 as a duplicate; same fix, in 16.3.5 — not re-measured here yet |
| [#97802](https://github.com/vercel/next.js/issues/97802) | Turbopack compilation saturates the container before rendering anything | not attributable to a version: see below. [#98581](https://github.com/vercel/next.js/pull/98581) (merged Sep 16, in `16.4.0-canary.34`) doesn't move it: cold build peak 5,161 MB on canary.33 and 5,279 MB on canary.35 (`next-leak build`); under 4 GB neither finishes compiling in 600 s, under 5 GB both compile in about a minute | **open** — the other fix from Vercel, [#98611](https://github.com/vercel/next.js/pull/98611), is still a draft |
| [#98707](https://github.com/vercel/next.js/issues/98707) | `next dev`: a route handler compiled after N pages costs ~16 MB × N | reproduced independently (10 pages, 34 handlers, Node 24.18): 851 MB on `16.3.0-canary.100`, **2,354 MB on canary.101**, 1,704 MB on 16.3.5; 1,461 MB requesting the handlers first | **open** — the reporter's bisect to `16.3.0-canary.101` holds |
| [#92287](https://github.com/vercel/next.js/issues/92287) | Cache Components: unbounded `arrayBuffers` under load | 37.5 MB of arrayBuffers held between collections, 37x what it retains (16.3.1) | **open** |
| [#84884](https://github.com/vercel/next.js/issues/84884) | axios + `AbortSignal` in middleware: a reference cycle through undici's `Request` finalizer, closed when Turbopack's scope hoisting inlines axios's `composeSignals` | +17.02 MB/1000 req on 16.3.5 (Node 24.18), +4.62 (Node 24.21); flat with scope hoisting off | **open** — still leaks on 16.3.5 and 16.4.0-canary.29; fix proposed in undici ([nodejs/undici#5822](https://github.com/nodejs/undici/pull/5822)); workaround: `experimental: { turbopackScopeHoisting: false }` |
| [#89091](https://github.com/vercel/next.js/issues/89091) | zlib retention on mid-stream aborts | +42.5 MB/1000 aborted req on 16.1.5; **+0.03 on 16.3.1** | closed |
| [#95094](https://github.com/vercel/next.js/issues/95094) | Middleware `setTimeout` ids retained by the sandbox | 112 MB retained; flat after the fix | fixed in 16.3.0 |
| [#94890](https://github.com/vercel/next.js/issues/94890) | Router LRU cache doesn't count its keys | 26.7 → 71.9 MB | fixed in 16.3.0 |
| [#94919](https://github.com/vercel/next.js/issues/94919) | Retention on client aborts | 39 → 139 MB · [with a caveat](#scope-and-limits-read-before-filing-issues) | fixed in 16.3.0 |
**#97802, and a measurement of ours that did not hold up.** Earlier versions of this
table said the regression was bisected to 16.3.0, on the strength of a 16.2.12 arm
that peaked around 2 GB while 16.3.x pinned the 4 GB ceiling. Re-measured on
2026-09-16 in a real cgroup, that comparison falls apart:
`turbopackRustReactCompiler` does not exist before 16.3, so 16.2.12 rejects the key
and silently compiles through the Babel React Compiler while every 16.3 arm uses the
Rust one. Hold the version fixed and change only the compiler and
`16.3.0-canary.100` goes from 4,096 MiB with 12.3M at-limit events to 2,250 MiB with
zero. Give the Babel arms 2,400 s and neither 16.2.12 (2,180 MiB) nor 16.3.5
(1,692 MiB) ever reaches `Compiled successfully` — the low peak was unfinished work,
not headroom. With the compiler equalised and 6 GB of room, 16.3.5 is the only arm
that finishes the build at all, and what kills 16.2.12 and `canary.0` happens after
compilation, in prerendering. So this row no longer claims a version: the fixture
does not separate 16.2 from 16.3.
Two things worth taking from this if you measure builds yourself: when every arm
pins at exactly the cgroup ceiling, the ceiling is the measurement and not the
versions, so the peak cannot be the verdict; and an arm that never reaches the end
of compilation is not an arm that fits, however low its peak looks.
The closed ones are kept deliberately: a tool that only lists open bugs
looks impressive until the bugs close, and what those rows show is that the
measurements matched what the fixes turned out to be. #94919 is the sharpest —
the PR that closed it discarded the RSC-WeakMap hypothesis in the title and
attributed the leak to native zlib retention instead, which is the same
mechanism the #89091 measurement had already isolated — and re-measuring #89091
on 16.3.1 (2026-08-18) shows it gone, from +42.5 MB per 1000 aborted requests
down to +0.03, which is the same fix arriving from the other direction.
The full causal chain, measured on that same issue: leak found (28.7 -> 138.9 MB
across 8 cycles), the workaround from the thread applied (`clearTimeout(id)`
inside the callback), same app re-measured with identical parameters:
**27.8 -> 25.6 MB, flat**. That is what a diagnostic tool should prove - not
that installing it saves memory, but that what it points at is the real cause.
Across ~25 healthy routes on production applications (PPR, MDX, Auth.js,
Sentry, i18n), it reported **zero false positives**.
Your self-hosted Next.js server's memory climbs until Node gives up:
```
FATAL ERROR: Reached heap limit Allocation failed - JavaScript heap out of memory
```
Under Docker or Kubernetes you may not even get that: the process is `OOMKilled`,
the container exits with **code 137**, and the restart wipes the evidence before
you can look at it. Almost every report of this ends the same way — *"please
provide heap snapshots taken after forced GC"* — which almost nobody produces
correctly. `next-leak` runs that controlled measurement for you and answers with
evidence a maintainer would accept.
The answers, all valuable:
1. **You don't have a leak** — the spike is transient and drains during idle (the most common case).
2. **Something is filling up, not leaking** — a bounded cache on its way to its ceiling, which grows every cycle and still is not a leak.
3. **The leak is in your code (or a dependency)** — named down to the source file when possible.
4. **It looks like framework internals** — with a ready-to-file issue draft.
## Quickstart
```bash
# 1. Your app must build with standalone output — in next.config:
# output: "standalone"
next build
# 2. Measure it
npx next-leak .
```
For each discovered route, in a fresh process, it runs the validated ritual:
```
warm-up → forced GC → baseline snapshot → [load → idle → GC → sample] ×4 → snapshot
```
The verdict comes from the **shape of the post-GC curve**: retained heap that
keeps growing every cycle is a leak; growth that flattens is warm-up. Where the
heap sits is noise — 40 MB and 400 MB say nothing on their own — so only the
shape is judged. The one absolute number involved is the gate a cycle's growth
must clear to count, and above 5000 requests per cycle it scales with the
traffic that cycle served — so in that range changing `--requests` changes how
long the run takes and not what it decides. Below 5000 the gate stops shrinking
and sits on the instrument's noise floor instead, so less traffic really does
buy a less sensitive run: that is the trade `--quick` makes at 2000 requests.
Every report prints the gate it used.
## Options
| Flag | Default | What it does |
|---|---|---|
| `--routes
` | all | Only measure these routes (comma-separated templates or prefixes) |
| `--cycles ` | 4 | Load cycles per route (min 3). The first is dropped as warm-up, so the verdict sees `n − 1` deltas — at 3 it sees two |
| `--repeat ` | 1 | Measure each route `n` times, each from a fresh server, and judge it on all of them (max 10). The run takes `n` times as long. Routes whose repetitions disagree are reported `inconclusive`, and the spread of growth rates is printed either way. More cycles watch one process for longer; repetitions watch different ones, which is where the variance lives — three runs of one Next build measured 602, 826 and 875 MB retained, and a fourth measured 39 MB |
| `--requests ` | 5000 | Requests per cycle. Raises sensitivity as well as duration: the growth gate scales with it, down to a noise floor around 5000 |
| `--connections ` | 100 | Concurrent connections |
| `--idle ` | 30 | **Maximum** wait before each sample; the run continues as soon as the heap settles |
| `--warmup ` | 200 | Requests before the baseline snapshot. Lower it on apps that cache per request: warm-up fills those caches and the baseline then measures the warm-up, not the app. The run says so when it happens |
| `--max-old-space ` | 512 | Heap cap of each measured process. Raise it for apps whose legitimate working set is larger, or they die under measurement |
| `--ready-timeout ` | 60 | How long each measured process gets to start listening. Raise it for apps that boot slowly. A process that never listens reports whatever it wrote to stderr while trying |
| `--quick` | off | Fast preset (2000 requests × 4 cycles, 8s idle) — the exact profile the real-app validation ran with. Same cycle count as the default; what it trades away is traffic per cycle, so it sits on the noise floor and is less sensitive to slow leaks. Explicit flags override it |
| `--no-resolve` | off | Skip the second pass on inconclusive routes |
| `--self-check` | off | Measure a planted leak first to prove the harness works here. Costs one route's worth of time; a run that cannot detect 8 KB per request produces verdicts worth nothing |
| `--diff-all` | off | Diff snapshots for stable routes too |
| `--attribute` | off | **`build` only.** Also name *what* the worker retains, not only that it retains |
| `--output ` | `/.next-leak` | Where runs are written |
| `--write-config` | off | Write `next-leak.config.json` for the routes that need sample params, then exit. Never overwrites an existing file |
There is a second command for the other half of the problem:
```bash
# Measure the build itself, not a built server
npx next-leak build .
```
A large site can run out of heap while prerendering, before any server exists to
measure ([#97464](https://github.com/vercel/next.js/issues/97464)). That command
runs your build unmodified and samples the resident memory of each
static-generation worker. It needs neither a previous build nor standalone
output, and takes `--output` and `--attribute`.
The report also prints what the build's **own process** reached, separately from
the worker's figure and labelled *reported, not judged*. The two are never added
together: the parent sheds memory while workers climb — 1.43 GB down to 0.10 GB
over the same window on the #97464 reproduction — so summing them cancels the
finding the worker verdict rests on. It is there because a build can fail
entirely in the parent, during compilation or file tracing, where no worker
exists yet.
Dynamic routes need sample params in `next-leak.config.json` in your app dir:
```json
{
"params": { "lang": "en" },
"routes": { "/products/[id]": { "id": "42-{n}" } },
"headers": { "accept-encoding": "gzip, br", "cookie": "session=..." }
}
```
`--write-config` generates that file for you. It takes the *shape* of each value
from paths your build already prerendered, and makes the value itself move:
`post-0` becomes `post-{n}`, and a value with no trailing number gets one —
`seed` becomes `seed-{n}`. A value the build prerendered is the one value
guaranteed not to measure anything — every request hits the same warm cache
entry, so the route reads as flat whatever it retains, and that false negative
lands on exactly the leaks being reported now (`use cache`, `cacheComponents`
and ISR all key on the params). If your app answers 404 for params it never
prerendered, the run says so through its non-2xx count; drop the marker then.
When a run skips a route it prints the same fragment.
```json
```
- **`headers`** are sent with every request. Real traffic is not header-less:
compression, sessions and auth change which code paths run, and some leaks
only live on those paths.
- **`{n}` inside a param value** makes every request use a *unique* URL
(`{ "id": "item-{n}" }` → `/logs/item-1`, `/logs/item-2`, …). Leaks keyed by
URL — route caches, LRUs, bot traffic with varied tails — are invisible
without it.
- **`query`** appends a query string per route template
(`{ "/api/payload/[slug]": "weightKb=2048" }`).
- **`abandonAfterMs`** makes clients hang up mid-response, the way closed tabs,
load-balancer timeouts and bots do. Some leaks only exist on that path
(`ServerResponse` retained after an early disconnect; the RSC tee branch in
[#94919](https://github.com/vercel/next.js/issues/94919)). The clock starts
at the **first byte of the response**, so the cut lands mid-stream however
long the route takes to answer. Small values are the point: `4` means "read
the first chunk, then vanish". Requests abandoned on purpose are not counted
as failures.
- **`abandonFrom`** moves that clock to the request itself
(`"abandonFrom": "request"`). Use it for the opposite experiment: a client
that is already gone before the server produces anything. On a route slower
than the deadline the default never cuts early — against the reproduction
for [#84648](https://github.com/vercel/next.js/issues/84648), whose upstream
answers in 400 ms while its load generator cuts at 60 ms, first-byte reached
7% of requests and `request` reached all of them. It stays opt-in because a
deadline armed on connect loses the race to the first byte on fast routes,
which measures the wrong path silently.
`run.json` records what every load phase actually did — requests sent,
2xx, abandoned — so a run can be audited instead of trusted.
Before measuring, the CLI prints a duration estimate — a 60-route app under defaults is **hours**; narrow with `--routes` for iteration.
## What it tells apart
"Memory leak" is one name for six different situations. The verdict machinery
separates them, because each one has a different fix:
| Looks like a leak | What next-leak reports | How it knows |
|---|---|---|
| One-time warm-up growth (JIT, lazy caches) | `stable` | The first cycle is excluded from the verdict; warm-up flattens, leaks keep climbing |
| A route that is expensive, not leaky | `failed` under load it cannot sustain, flat once concurrency fits | Real leaks survive forced GC at any concurrency; saturation disappears when load drops |
| Growth that pauses and resumes (stepwise) | `leak` | A healthy route gives back 20-30% of its growth; a stepwise leak gives back nothing |
| A cache filling up under the load that measures it | `saturating` | A bounded store grows by less each cycle as new keys get rarer; a leak does not decelerate |
| Memory a forced GC reclaims that production never reclaims in time | `pressure` | Every verdict sample is post-GC; the peaks are sampled under load, and a ceiling every settled cycle comes back to is a regime, not an episode |
| Native/buffer memory with a flat JS heap | `leak (external)` or an explicit RSS note | Heap, `external` and RSS are sampled and judged separately |
| A leak in your code vs a dependency vs Next itself | `culprit: src/app/x/page.tsx (your code)` — or the package, or framework internals | Retainer chains mapped through the build's source maps |
| A run whose own evidence is weak | `low confidence` warnings, or the verdict is withdrawn | Every run audits itself: did the load land, did the heap settle, does one cycle carry the average, did the heap run into its own ceiling |
## Reading the verdicts
- **`stable`** — no growth this run could detect: across the cycles it ran, the
post-GC curve never cleared the growth gate printed at the foot of the
report. Before trusting a page of these, prove the instrument works where you
are running it: `--self-check` plants a leak of 8 KB per request and measures
it, under your Node build, your heap cap, your concurrency and your container
limits. On this machine it comes back at 8.16 MB/1000 requests against a
theoretical 8.0 — a harness that cannot see that is one whose flat curves mean
nothing, and the run says so when nothing vouched for it. That is not proof of absence, and the wording matters — the verdict
is deliberately biased toward missing a leak rather than inventing one (a
single flat or falling cycle is enough to call a route stable), so a leak
that oscillates while it climbs can land here. To press harder, raise
`--cycles` — every extra cycle is another delta the verdict gets to see.
Raising `--requests` only helps from below 5000: above that the gate scales
with the traffic, so the longer run decides the same thing. If the heap is
flat but RSS keeps climbing, the report says so explicitly: that is an
allocator, external-buffer or fragmentation problem, not a JS-heap leak.
- **`leak`** — the report names the culprit when attribution resolves: your file (`culprit: src/app/x/page.tsx (your code)`), a dependency (package name), or framework internals. An `ISSUE-.md` draft is generated **when the evidence plainly supports the verdict** — a `leak` carrying low-confidence warnings (growth barely over the threshold, one cycle dominating the mean, too few cycles for its size) gets the verdict but no draft, because a draft is written to be pasted into someone else's tracker. If the leak is app-owned, the draft tells you **not** to file it upstream.
- **`saturating`** — every cycle grew, but by less than the one before, and the
last by less than half the first. That is the shape of a bounded store
running out of new keys, not of memory going missing. It matters because the
alternative was calling it a leak: a `use cache` route measured on Next
16.3.3 came out at +603 MB per 1000 requests that was entirely the cache
storing what it had been asked to store — the same route dropped to +88 MB
once the payload was removed. Because the shape requires every cycle to clear
the growth gate, a decelerating curve always ends the window still growing,
so where it settles is outside what was measured: these routes are
**measured again** with twice the cycles, like `inconclusive` ones. No issue
draft is generated. When the load was driving a cache with keys it had never
served, the report says so on any growing route and points at `{n%N}` to
bound the key set — measure again that way before believing the number.
- **`pressure`** — nothing is retained, and the process is still heading for a
ceiling. Every sample a verdict is computed from is taken after a forced GC,
and production runs none of those, so the retention verdicts above are
structurally blind to memory a full collection *does* reclaim but that the
runtime does not reclaim fast enough on its own. This is that case: the
post-GC curve is flat or falling, the peak sampled under load is far above
what the route retains, **and** every settled cycle reaches that height. On
the reproduction for [#92287](https://github.com/vercel/next.js/issues/92287)
the app allocated about 1 MB of `arrayBuffers` per request, passed 3 GB and
was OOM-killed — and the old verdict was `stable`, which is precisely the trap
this tool exists to warn other people about. A single high peak is *not* this:
one cycle that reached a ceiling for a reason that did not repeat stays
`stable` with a peak note, because an episode is not a regime. What separates
this from an app entitled to a large working set is not the shape of the
curve, it is that a working set survives the forced collection and lands in
what the route retains, which acquits it on the ratio alone. These
routes are not measured again (the run already saw the ceiling it is
reporting) and get no issue draft: the finding is real, but it is not
retention, so there is nothing for a snapshot diff to name. The fix is
usually allocation rate, response size or concurrency, not a missing
`delete`.
- **`inconclusive`** — the evidence does not decide. The run does not stop there: any inconclusive route is **measured again automatically**, with twice the cycles, and the second pass is what you see (`resolved at 8 cycles` next to the verdict). On the reproduction for [#95094](https://github.com/vercel/next.js/issues/95094), `--quick` alone reports `inconclusive` on three deltas and then comes back with the leak. `--no-resolve` turns the second pass off; when even that is undecided, the re-run command is still printed.
- **`failed`** — the route errored under load (auth redirects, POST-only endpoints). >1% non-2xx aborts measurement instead of measuring garbage. That's by design. A process that died of **heap exhaustion** is not one of these: it reports `leak`, because a route that could not survive its own load did not fail to be measured — it was measured right up to the point where it stopped fitting. The verdict comes from that outcome, not from the shape of the truncated curve, which is the same rule `next-leak build` applies to a static-generation worker that dies. The run prints the cycles it survived and the growth up to the death, and exits 0 with a finding rather than 1 with an error.
When a route is configured with a varying sample value (`{n}`) and *every* request comes back non-2xx, the run checks whether the value is the problem before blaming the route: it requests one value the marker would produce and one the build prerendered, and only when those disagree does it say so. An app with `generateStaticParams` and `dynamicParams = false` answers 404 for anything outside its param set, which is indistinguishable from a broken route in the counters alone. Bound the marker to the params that exist (`{n%N}`) or drop it.
## Peak pressure: `stable` is not the same as safe
Every verdict above is about what a route **retains** after idle and a forced
GC. That is the right question for a leak and the wrong one for an
`OOMKilled`: a process can climb to gigabytes under load, hand it all back
when the load stops, and still be killed at its peak. So each load cycle is
also sampled *without* collecting, and the highest value is reported next to
the verdict:
```
✔ /[slug] stable (-164.08 MB/1000 req) heap 261.9 MB → 265.7 MB → 35.4 MB → 36.0 MB
▲ peak pressure: peaked at 3145.7 MB rss under load while retaining 36.0 MB —
a container sized on what it retains dies on what it reaches
```
That is a real measurement of the reproduction in
[vercel/next.js#92287](https://github.com/vercel/next.js/issues/92287) on
16.2.2: no retention, and 3 GB reached under its own sustained load. The same
app on 16.3.1 under a shorter profile still reaches 544 MB against 33.8 MB
retained, so the shape has not gone anywhere. The note fires when the peak heap comes within
75% of `--max-old-space`, or when peak RSS is at least 8× the retained heap
and above 512 MB. A peak is the highest value *sampled* (every 250 ms), so it
is a lower bound.
A single high peak stays a note and leaves the verdict alone: one cycle that
reached a ceiling may have reached it for a reason that will not happen again.
When **every settled cycle** comes back to that height the verdict becomes
[`pressure`](#reading-the-verdicts) instead, because at that point the run is no
longer describing an episode, it is describing what the route does under load —
which is the number a container is sized against. The peak is not required to
climb, and asking it to would make the verdict unreachable: each cycle is
preceded by a forced collection and runs the same traffic, so the peak converges
on traffic × cost-per-request rather than ramping. Measured on the #92287
reproduction on 2026-09-24, the rss peaks across four cycles were 1229, 1344,
1369 and 1379 MB — an asymptote.
What the route retains, for this ratio, is the **floor** of its post-GC cycle
samples rather than the last of them. Those samples follow a forced collection
but can still carry memory the collector had not reached yet, and on that same
reproduction they swung between 45 MB and 217 MB inside a single run, which by
itself decided whether the note appeared at all.
If the measured process dies at the limit instead of merely approaching it,
the route fails saying exactly that, with the limit in force and how to raise
it.
### Memory a GC reclaims that production never reclaims
There is a third question again, and it is the shape of most of the leaks
reported in August: memory the process *holds between collections*, which a
forced GC takes back and a long-running server may never run one to take back.
Every verdict above is post-GC, so that class is invisible to it by
construction.
Each cycle is therefore read twice — once before any forced collection, once
after — and the gap between them is reported when it is large:
```
✖ /posts/[slug] leak (+0.16 MB/1000 req) heap 27.1 → 26.3 → … → 27.9 MB
driven through ISR revalidation (revalidates every 3600s; without it the load
would serve the cache)
▲ unreclaimed: held 4.72 MB of arrayBuffers between collections that a GC took
back (4.7x what it retains) — a forced GC reclaims this, a long-running
process may not run one often enough to
```
A real measurement of the reproduction in
[#96533](https://github.com/vercel/next.js/issues/96533), whose reporter
accumulated 1.16 GB of `arrayBuffers` over four days against a flat JS heap.
The note fires on the **gap**, not on a trend: that pre-collection series
oscillates rather than climbs, and a rule keyed on it climbing reported nothing
at all. It needs both a floor (2 MB) and a ratio (0.35× what the route retains),
because the absolute size alone does not separate this from an ordinary leak.
Its limit, stated on the line itself: the reading is taken seconds after load,
not the hours a production process runs between full collections, so it
includes memory that had not been collected yet. It never changes the verdict.
### ISR routes are driven, not served from cache
A route with a revalidation period serves its cache unless the request carries
the build's own `x-prerender-revalidate` header. Measured on that same app: the
identical run reports `leak` with the header and `stable` without it. next-leak
reads `previewModeId` from `.next/prerender-manifest.json` and drives those
routes itself; a header you set in `next-leak.config.json` wins untouched. When
the manifest cannot supply one, the route is reported `not exercised` with no
verdict, because a flat curve measured against a static cache says nothing about
the app.
## The tool grades its own measurement
A leak detector is an instrument, and a miscalibrated instrument doesn't fail
loudly — it reports confident, wrong numbers. So every run is audited against
its own evidence, and anything that undermines a verdict is printed next to it:
```
✖ /api/items leak (+3.10 MB/1000 req) heap 28.4 MB → 41.9 MB → …
⚠ low confidence: cycle 2 landed 4310 of 5000 requests (86.2%) — the route
saw less traffic than reported
```
What gets checked: whether the heap actually held still before each sample,
whether the requests you asked for really landed, whether an early-disconnect
run disconnected anything, whether one cycle dominates the average, whether
the growth barely clears the noise floor, and whether the heap came close
enough to its own cap that the curve was clipped by the ceiling rather than by
the app.
When the run didn't observe what a `leak` verdict requires — the heap never
settled, or an abandonment run abandoned nothing — the verdict is **withdrawn**
and reported as `inconclusive`, with what was measured still on the record. A
withdrawn verdict produces no `ISSUE-*.md` draft: only a verdict the evidence
supports is worth pasting into someone else's tracker. Caveats that don't
overturn a verdict still travel with the draft, under *Measurement caveats*.
Stable verdicts are never withdrawn. Quietly missing a leak costs you less
than a false accusation, and the warnings are on the report either way.
## Every run leaves evidence
```
.next-leak//
├── report.html # heap curves per route — self-contained, opens offline
├── ISSUE-.md # issue draft per leaking route (Next.js bug-template shape)
├── run.json # everything, machine-readable: environment, per-phase
│ # timings, heap AND RSS samples per cycle, what each
│ # load phase actually did, and the confidence audit
└── -/ # raw baseline/after .heapsnapshot per route
```
`report.html` is the one you send to someone else. It is a real run below —
three routes measured with `--self-check`, on the reproduction this repo tests
against:
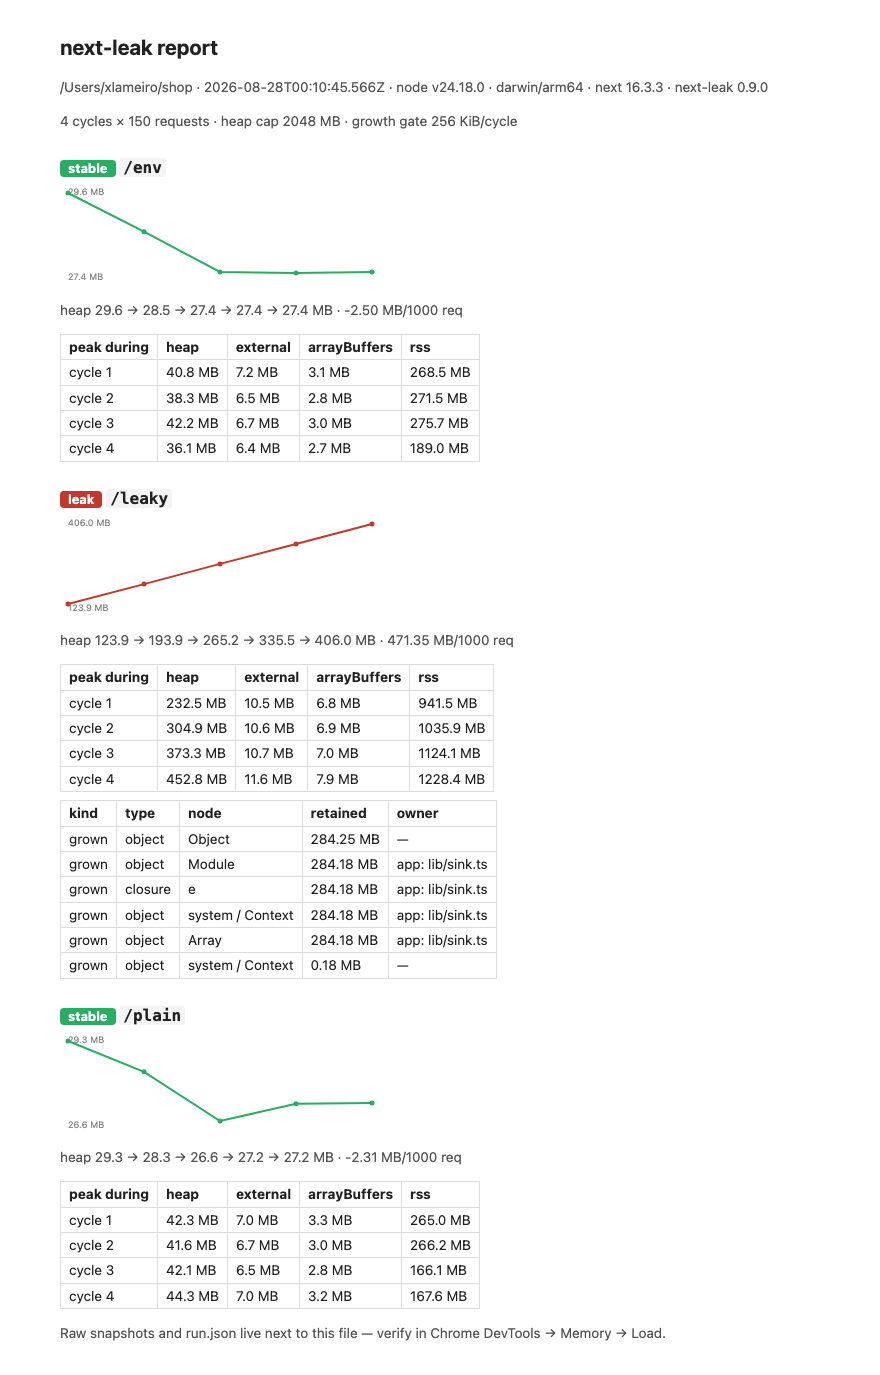 Per route it draws the post-GC curve, the peak reached *during* each cycle
across heap, external, arrayBuffers and RSS, and what grew between the two
snapshots — with its retained size and, when the source maps resolve it, the
file that owns it. No JavaScript, no external requests, no
fonts to fetch: it opens offline from a CI artifact. The file above is
[`docs/report-example.html`](./docs/report-example.html) if you want to poke at
the markup.
Snapshots are the ground truth: load them in Chrome DevTools (Memory → Load → Comparison) and check every claim yourself. Runs accumulate — each keeps its snapshots (tens of MB per route); delete old timestamp folders when done.
## Why not just use…
| | What it gives you | Where it stops |
|---|---|---|
| **Chrome DevTools** | The ground truth: two snapshots and a comparison view | You reproduce the load, force the GC, pick the moments and read the retainers yourself. Doing it *correctly* is the hard part |
| **[memlab](https://github.com/facebook/memlab)** | A superb heap-analysis engine — next-leak **uses it** to parse snapshots | It is built around browser scenarios you script. It does not drive HTTP load against your routes, and it knows nothing about Next.js route manifests or your bundle's source maps |
| **[clinic.js](https://github.com/clinicjs/node-clinic)** | Broad Node performance profiling | [Its own README](https://github.com/clinicjs/node-clinic#readme) states it is no longer actively maintained |
| **`--inspect` + manual snapshots** | Full control | Same as DevTools, plus you must keep the process, the load and the snapshots in sync by hand |
What next-leak adds is not analysis — it is **the controlled experiment around
it**: a fresh process per route, warm-up before the baseline, forced GC and an
adaptive idle before every sample, an audit of whether the load it claims to
have sent actually landed, and a verdict from the curve's shape rather than
absolute sizes. Then it maps the retaining objects back to *your* source files
through the build's source maps.
## Scope and limits (read before filing issues)
- **Supported (default command):** App Router · `output: "standalone"` · Node ≥ 22 · Linux/macOS. Pages Router, non-standalone, and Windows are rejected with a clear message.
- **Monorepos work unchanged.** A workspace build does not put `server.js` at
the root of `.next/standalone`: Next keeps the app's path relative to the
workspace root, so an app in `client/` ships its server at
`.next/standalone/client/server.js` with `node_modules` hoisted above it.
Point the tool at the app directory as usual — it looks there too. Do not
flatten that tree by hand: on a pnpm workspace the moved `server.js` cannot
resolve `next` any more, because what sits in `standalone//node_modules`
are relative symlinks into `../../node_modules/.pnpm/`, and a level up they
point outside the tree. An npm workspace survives the move — it puts no
`node_modules` beside the app at all — which is why the same build can serve
by hand and still be unmeasurable.
- **Sample values can vary per request.** `"slug": "post-{n}"` gives every
request its own URL — the shape of bot traffic and of a cache that never
repeats a key. `"slug": "post-{n%200}"` cycles through exactly 200 distinct
values, revisiting them across cycles, which is the shape the reported leaks
actually have ([#96533](https://github.com/vercel/next.js/issues/96533)
revalidates a fixed set of posts;
[#92287](https://github.com/vercel/next.js/issues/92287) turns on how many
keys a cache holds at once). A value carrying both markers is rejected before
the run starts.
- **`next-leak build `** measures the build instead of the server, and needs
neither a previous build nor standalone output — it runs `next build` and
samples the resident memory of each static-generation worker, which is where
large sites run out of heap while prerendering
([#97464](https://github.com/vercel/next.js/issues/97464)). It does not apply
to projects using `experimental.workerThreads: true`: a worker thread has no
resident memory of its own to sample, and the run says so instead of
reporting a number that would be measuring the parent.
- **`next-leak build --attribute`** additionally names *what* the worker
retained, by signalling it for a pair of heap snapshots. **Opt-in, and slow
by nature:** the signal makes the worker write its whole heap to disk, which
on the #97464 reproduction has stalled a build for minutes at a time and
once for an hour and a half. Use it on a reproduction you are investigating,
not on a build you need to finish. It also covers only a low slice of the
curve, and says which: a snapshot weighs roughly 0.4x to 0.8x the worker's
resident size — both captures happen well below the ceiling, and the report
states what share of the observed growth they span (19% on that
reproduction, whose worker peaks near 4 GB).
That ceiling is not the file's size. memlab reads `nodes`, `edges` and
`locations` as typed arrays in chunks and only parses the rest, so what has
to fit in a 512 MB V8 string is everything else — and on a leaking snapshot
that is almost nothing. A 1342.9 MB capture of a leaking route parsed 2.4 MB
of JSON and diffs fine; a 2227.5 MB one whose `strings` section alone was
868.9 MB is refused, and the message names 869 MB rather than 2227 MB.
- **A slow snapshot is not a failed route.** `v8.writeHeapSnapshot` blocks the
measured process until the file is on disk, so the control channel goes
silent for as long as the write takes — and the worse the leak, the longer
that is. The wait is judged by bytes reaching disk, not by a clock: a
snapshot that is still growing is given as long as it needs, while five
minutes with nothing written is treated as a wedged process and said so. If
the final snapshot cannot be taken at all, the run keeps its verdict — the
curve is already complete by then — and reports the missing attribution
instead of discarding the route. Measured on the
[#84648](https://github.com/vercel/next.js/issues/84648) reproduction, whose
4.2 GB capture outlasted every fixed deadline worth setting.
- **Architectures:** verified on **arm64 and x64** (linux/amd64 in Docker) — same app, same parameters, same verdicts.
- **Attribution** (naming the file) needs a Turbopack build with server sourcemaps — the Next 15+ default. On webpack builds the registry is empty by design and findings degrade to `unattributed` with raw retainer chains; measurement itself does not depend on it. Note that `output: "standalone"` + `--webpack` produced a bundle that could not start at all on `16.3.0-canary.90` (missing `@swc/helpers`), independently of this tool.
- Empirically validated on Next **15.5.4, 16.0.x, 16.1.5, 16.2.x, 16.3.0/16.3.1 and 16.3-canary** (incl. Sentry, OpenTelemetry, PPR and i18n apps), against the public reproductions attached to real issues (open and since-fixed). Most recent measurements, 2026-08-17/18: the runtime path on 16.2.12 and 16.3.1-canary.18, the build path on 16.2.12 and 16.3.1. The contracts it relies on are stable since Next 13–14, but older versions are untested.
- **Each measured process runs under a 512 MB heap cap** by default, so a leak
reaches a ceiling in minutes instead of the hours a production container
takes. An app whose legitimate working set is larger needs
`--max-old-space`, or every route dies as an OOM that is not the app's
fault. When a run's heap gets close to the cap, the report says so.
- Borderline routes can flip between `stable`/`leak` across runs — more cycles resolves this.
- The [#94919](https://github.com/vercel/next.js/issues/94919) reproduction ships
a **custom Express server and deliberately no standalone output**, which this
tool cannot measure as published. The figure above comes from the same app
built with `output: "standalone"` — the leak is there too, but that is Next's
server under test, not the reporter's middleware chain. Instrumenting their
own server by hand (same `--import` bootstrap, no CLI) showed the same shape:
post-GC heap 43 → 56 MB and arrayBuffers 0.2 → 10.7 MB over four cycles.
- The **peak-pressure** thresholds are calibrated against one reproduction measured in three regimes plus the bundled fixture, not against the ~40-route validation set the verdicts were tuned on. A peak note never changes a verdict, so the cost of a false one is noise, not a false accusation — but treat the exact thresholds as young.
- The measured app runs with its real environment: routes that call external services will call them under load. Scope with `--routes` and moderate `--requests` accordingly.
## Development
```bash
pnpm install
pnpm typecheck && pnpm test && pnpm build
pnpm pack:smoke # release gate: installs the real tarball and measures the fixture app
pnpm test:mutation # Stryker — slow; run before releases, weekly in CI
```
`pnpm build` also regenerates [THIRD-PARTY-NOTICES.md](./THIRD-PARTY-NOTICES.md)
from the build's metafile and runs `scripts/check-bundle.mjs`, which fails the
build if browser tooling ever gets back into `dist/`. Commit the regenerated
notices when a dependency changes.
CI runs typecheck, tests, build, `pnpm audit --prod` and the pack smoke on
Node 22 and 24; mutation testing runs weekly and uploads its report.
## License
MIT