<div align="center">

<img src="./assets/img/Hero.png" width="100%"
     alt="DeepSeek Harness hero banner: conversations distilled into layered memories and recalled before every model step — chat bubbles dissolve into three progressively brighter light layers flowing into a frosted-glass capsule with a glowing orb and gradient track (tick labels: 日常·工作·智能·关闭), with light threads looping back to suggest recall">

# dsh-prime-memory

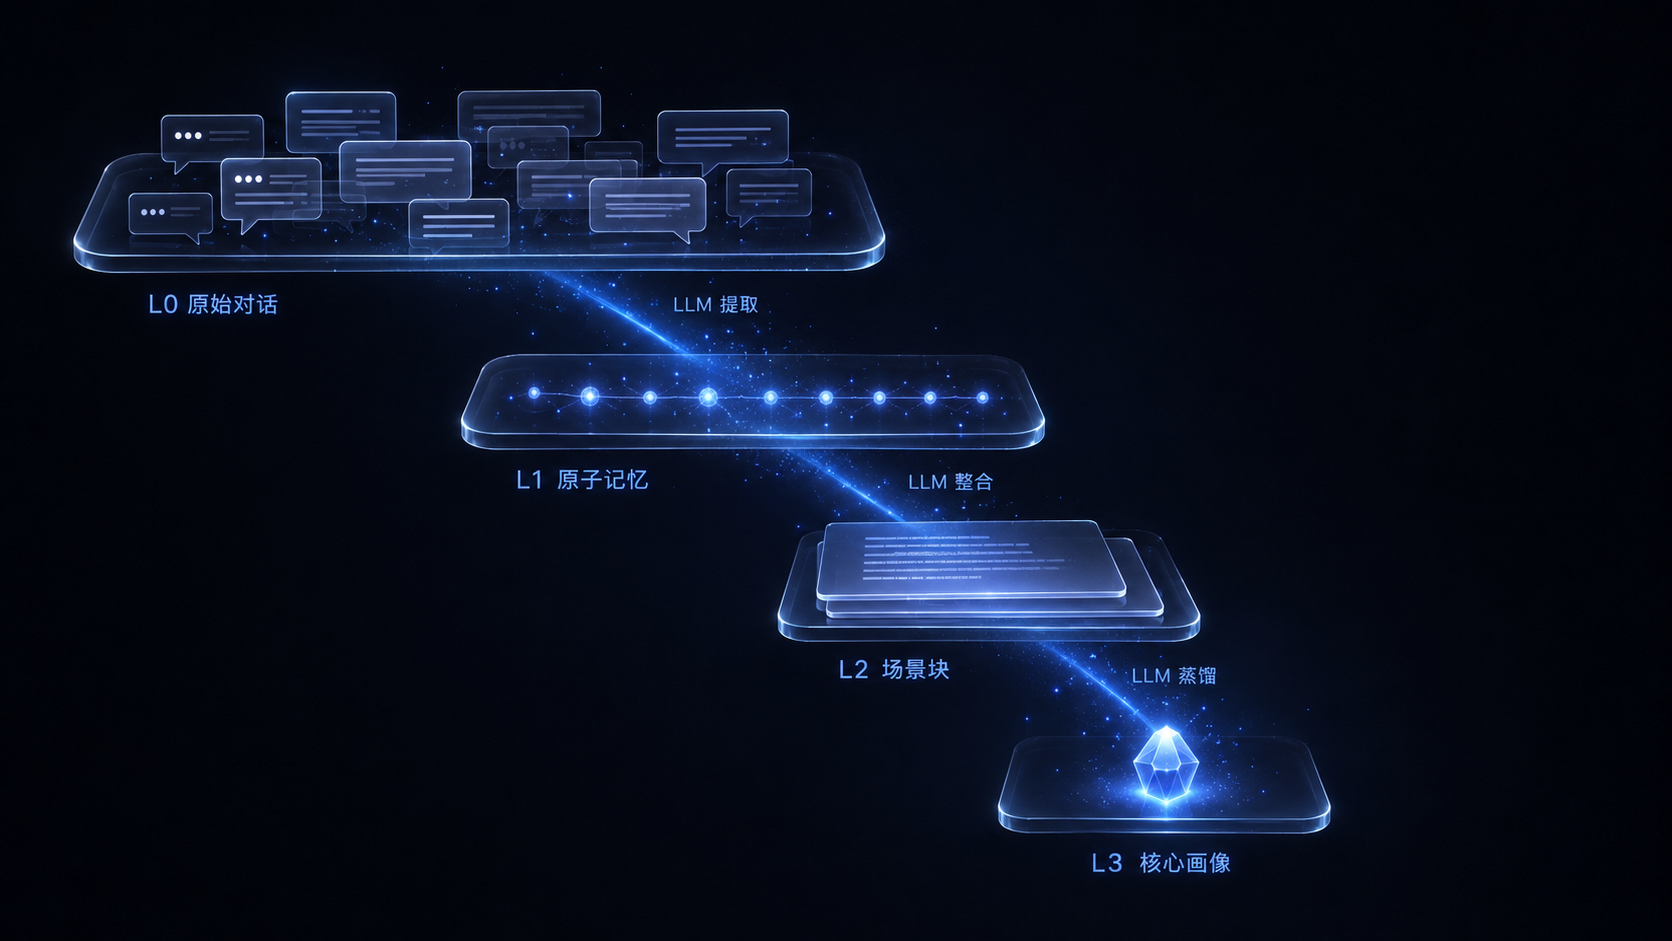
**A layered distillation memory plugin for DeepSeek Harness: conversations are processed in the background through L0 capture → L1 atomic memories → L2 scene consolidation → L3 persona distillation, and relevant memories are automatically injected into context before every model step — neither the user nor the model needs to do anything.**

[简体中文](README.md) · [Latest release](https://github.com/drscrewdriver/dsh-prime-memory/releases/latest) · [Report issues](https://github.com/drscrewdriver/dsh-prime-memory/issues)

[![npm version](https://img.shields.io/npm/v/dsh-prime-memory?color=6f83ff&style=flat-square&label=npm)](https://www.npmjs.com/package/dsh-prime-memory)
[![DSH 0.2.0-rc.1](https://img.shields.io/badge/DSH-0.2.0--rc.1-8b5cf6?style=flat-square)](https://github.com/deepseek-ai/deepseek-harness)
[![MIT License](https://img.shields.io/badge/license-MIT-536990?style=flat-square)](LICENSE)

</div>

<details open>
<summary>🌐 Language</summary>

- [中文 README](./README.md)
- [English README](./README.en.md)
- [日本語 README](./README.ja.md)
- [한국어 README](./README.ko.md)
- [README en français](./README.fr.md)
- [README auf Deutsch](./README.de.md)
- [README in italiano](./README.it.md)
- [README на русском](./README.ru.md)
- [README en español](./README.es.md)
- [安装指南（中文）](./INSTALL.md)
- [Installation guide (English)](./INSTALL.en.md)
- [日本語インストールガイド](./INSTALL.ja.md)
- [한국어 설치 안내](./INSTALL.ko.md)
- [Guide d'installation (français)](./INSTALL.fr.md)
- [Installationsanleitung (Deutsch)](./INSTALL.de.md)
- [Guida all'installazione (Italiano)](./INSTALL.it.md)
- [Руководство по установке (Русский)](./INSTALL.ru.md)
- [Guía de instalación (Español)](./INSTALL.es.md)
- [更新日志（中文）](./CHANGELOG.md)
- [Changelog (English)](./CHANGELOG.en.md)
- [日本語 changelog](./CHANGELOG.ja.md)
- [한국어 changelog](./CHANGELOG.ko.md)
- [Changelog en français](./CHANGELOG.fr.md)
- [Changelog auf Deutsch](./CHANGELOG.de.md)
- [Changelog in italiano](./CHANGELOG.it.md)
- [Changelog на русском](./CHANGELOG.ru.md)
- [Changelog en español](./CHANGELOG.es.md)

</details>

## DSH Version Compatibility Matrix

| DSH version | settings registration API | Status |
|---|---|---|
| 0.1.1-rc.2 | `settings.register()` (live scope) | ✅ Verified |
| 0.1.2-rc.1 | `settings.register()` (fallback available) | ⚠️ Inferred from framework docs, not field-tested |
| 0.1.3-rc.1 | `settings.register()` (fallback available) | ⚠️ Not field-tested (0.1.3+ namespaces became plain strings; this plugin is compatible) |
| 0.1.5-rc.2 | `settings.register()` (fallback available) | ⚠️ Not field-tested; Session V3 surface semantics and input-bar/settings slots pending regression |
| 0.2.0-rc.1 | `settings.register()` (live scope) | ✅ Current adaptation line (event wiring agent/session-start → agent/created) |

> Compatibility mechanism: settings registration uses a three-way runtime branch
> (`register` → `installSection` bridge → always-on degradation); see the 0.11.0 entry
> in [CHANGELOG.md](./CHANGELOG.md). `dsh.plugin.json` declares
> `engines.dsh` 为逐 rc 精确枚举串（0.1.0-rc.2 → 0.2.1-rc.5，20 rc）.

## Getting Started

Requires Node ≥ 22.16. Two invocation styles — the `npx` prefix can replace `dsh` in
any command below:

```bash
# Option 1: run the official CLI directly via npx (no pre-installed dsh; version can be pinned, e.g. dsh-prime-memory@0.8.4)
npx -y @deepseek-ai/dsh plugin --profile web add dsh-prime-memory

# Option 2: with the dsh CLI installed (dsh is a pnpm forwarder; npm i -g pnpm first if missing)
dsh plugin --profile web add dsh-prime-memory

# Alternative sources: GitHub repo / local path (dev & debugging, link: points at the repo; npm run build + restart dsh to apply)
dsh plugin --profile web add https://github.com/drscrewdriver/dsh-prime-memory
dsh plugin --profile web add /path/to/dsh-prime-memory
```

### Install via an AI Agent (Recommended)

If your current agent can run terminal commands, send it this message as-is:

```text
Please install the dsh-prime-memory plugin for the web profile of DeepSeek Harness.

Run only the two commands below and do not modify any other profile:
dsh plugin --profile web add dsh-prime-memory
dsh --profile web --dump-config

Confirm that dsh-prime-memory appears in the output, then report the result to me.
Do not close or restart my running DSH yourself; after installation, remind me to manually restart the DSH Web Host.
```

The agent should report the installation result and explicitly tell you whether
`dsh-prime-memory` has appeared in the configuration.

This package declares a `dsh.bundle` composition layer (`cordis.patch.yml`); after
installation the **plugin entry is mounted automatically** — no need to hand-edit
`$DSH_HOME/profiles/web/cordis.patch.yml`. Then restart DeepSeek Harness and verify:
the appearance of `conversations/ records/ scenes/` and `memory.db` under
`~/.dsh/memory/` means the plugin applied successfully; the "Memory" page in settings
and the mode pill in the input bar mean the client half is ready.

> ⚠️ **Security note**: installing a plugin = running third-party code with your
> privileges. This plugin reads session content, writes files in its data directory,
> and calls the LLM/embedding services you configured; if that concerns you, review
> the source first (`src/`).

**Uninstall**: `dsh plugin --profile web remove dsh-prime-memory` + restart. Data
stays in `~/.dsh/memory/`; delete the whole directory manually if you don't need it.

### Development from Source

```bash
git clone https://github.com/drscrewdriver/dsh-prime-memory
cd dsh-prime-memory
npm install && npm run build
dsh plugin --profile web add .        # link: install; after code changes, npm run build + restart dsh
npm run smoke                         # smoke test (rebuild first: see command below)
npx tsc src/smoke.ts --outDir dist-smoke --module nodenext --moduleResolution nodenext --target es2022 --strict --skipLibCheck --esModuleInterop
```

## Runtime Data Flow

<p align="center">
  <img src="./assets/readme/flow.svg" width="100%"
       alt="Runtime data flow: session events from User and Assistant (left) flow into the plugin (L0 capture, L1–L3 distillation, retrieval, memory tools), which injects relevant memories into the DeepSeek Harness core (right) at agent/pre-step; distillation reuses the core's ctx.llm and data is dual-written to ~/.dsh/memory/">
</p>

The plugin attaches to DSH-native event seams (`session/event` for capture,
`agent/pre-step` for injection) and reuses the host's `ctx.llm` for distillation. Recall
is presented as **message-side injection**: relevant memories enter the conversation as a
synthetic message placed right before the user's new message, rendered as a
**"Context injection · memory"** row in the chat flow (expand to see the hits) — so you
can see "memory at work" directly. Injected content is bounded by length and
time budgets — oversized lines are truncated (pointing the model at the memory tools for
the full text) and a timed-out recall silently skips that turn, never slowing the chat.
**Per-session dedupe**: a memory already injected in this session is not injected again
(the model's context already holds it — follow-up questions on the same topic save
tokens); the record resets when the context is compacted or cleared, so memories can
flow back in, and an updated memory (new id after a content change) is never held back
by the old suppression. **Freshness weighting**: recall ranking applies a soft weight
`relevance × max(0.5, 0.5^(days since last update / 30))` — among candidates of similar
relevance the fresh one wins (slots rotate naturally), while a strongly relevant old
memory still recalls fine (the floor caps its loss at half a ranking score, so
long-lived facts never sink); tune via `recall.decayHalfLifeDays`, `0` disables. It
also registers three model-callable memory tools: `memory_search` /
`conversation_search` / `memory_read_scene`.

**Cost dashboard**: every distillation LLM call (extract / dedup / L2 / L3) writes its
token cost to a SQLite detail table keyed by `provider/model` (configurable retention,
default 365 days with rolling cleanup on write; accounting failures only log a warning
and never block distillation). Visualize it under Settings → Memory → the **Cost** tab:
per-model trend lines (day/week/month granularity + last-N-days window + L1/L2/L3 layer
filter), a layer × time-window table (calls / output & reasoning tokens / mean / median),
and per-model totals — distillation overhead at a glance. Input is counted in characters
(DSH streaming usage carries no input tokens); output and reasoning in tokens.

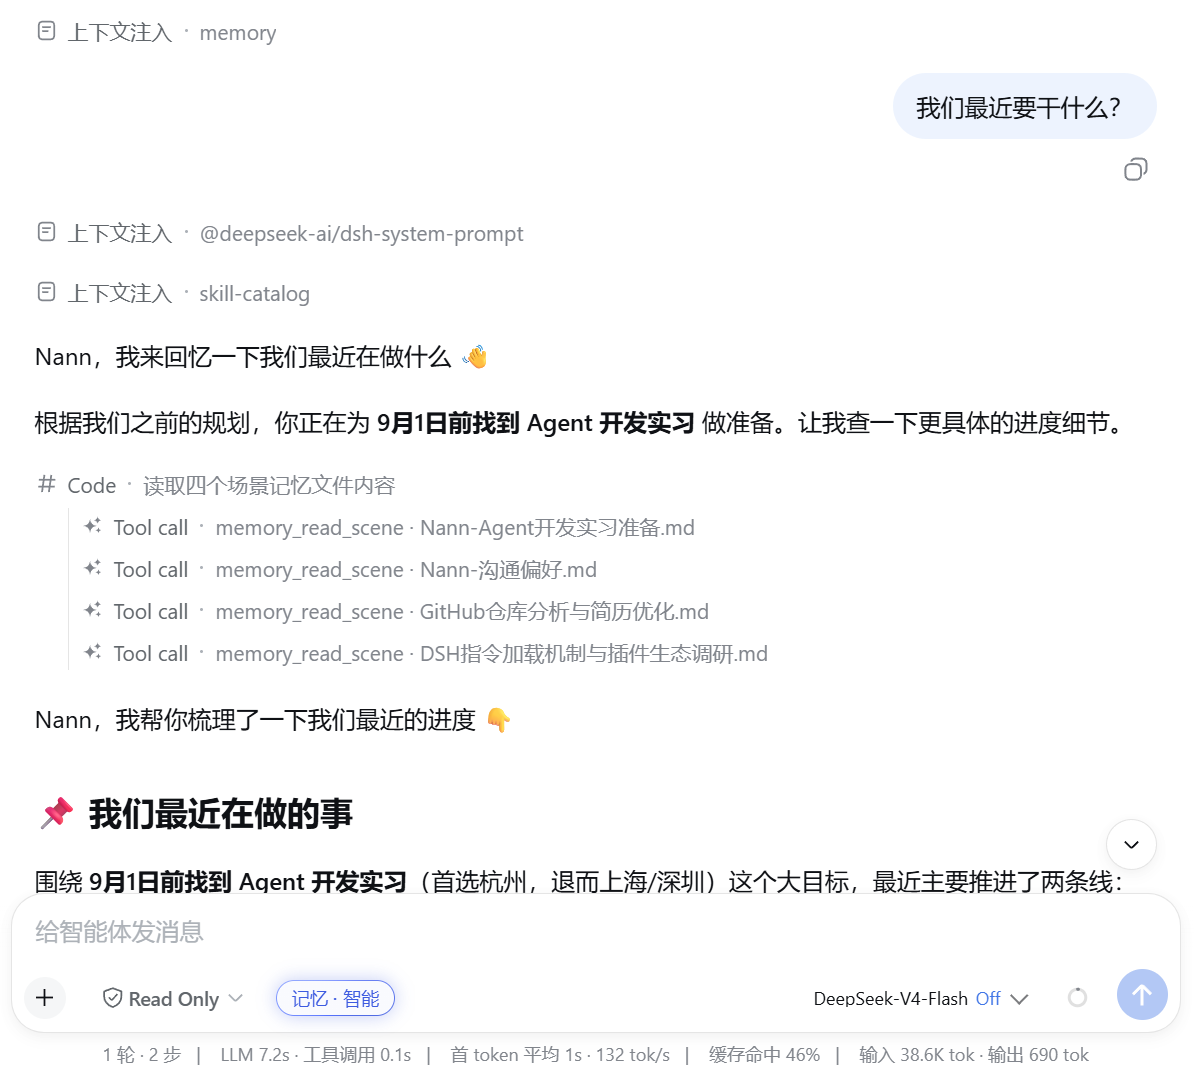
In action: the "Context injection · memory" row surfaces relevant memories first, and
the model then calls `memory_read_scene` directly to read scene blocks before answering
from memory:

<p align="center">
  <img src="./assets/img/MemoryTools.png" width="60%"
       alt="Real conversation UI (light theme): a "Context injection · memory" row sits above the user's message asking about recent plans; the assistant lists 4 memory_read_scene tool calls (with scene-block .md filenames as arguments) before answering from memory">
</p>

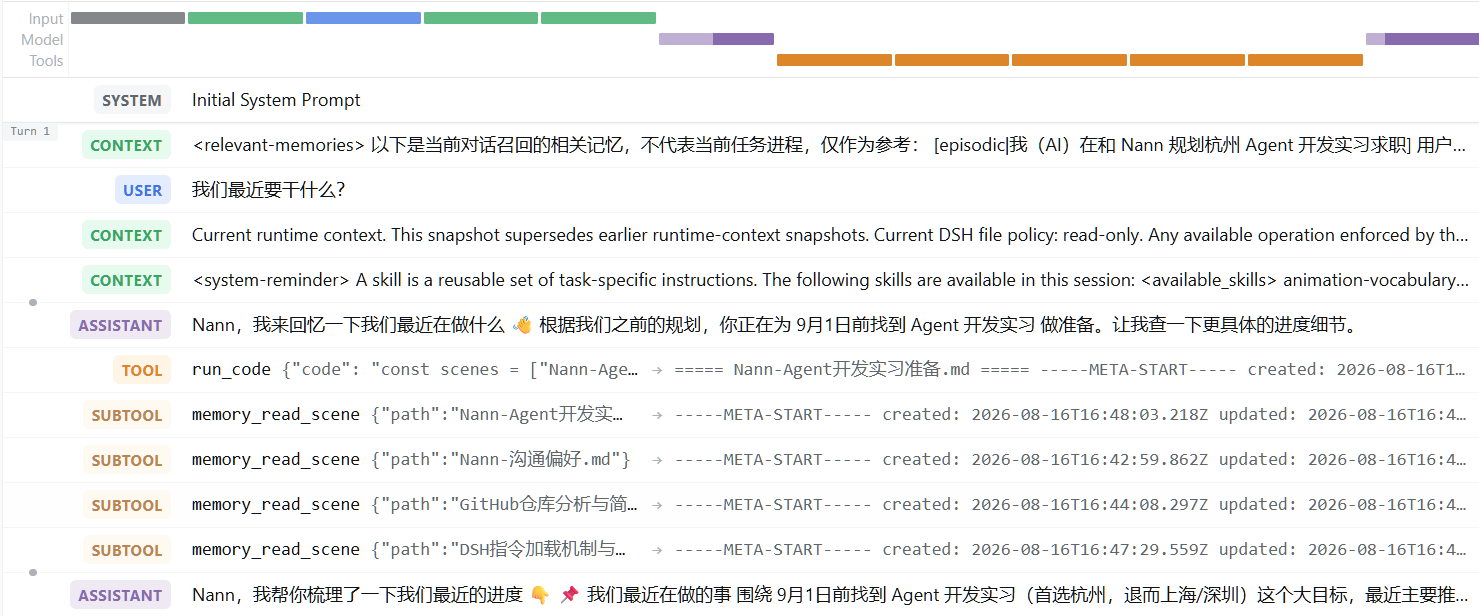
In restricted sessions where only the code-execution entry point is available, the model
reaches the memory tools indirectly through `run_code` (nested as SUBTOOL calls in the
trajectory view):

<p align="center">
  <img src="./assets/img/ToolTrajectory.png" width="80%"
       alt="Tool-call trajectory view: a colored timeline on top and a step list on the left (SYSTEM/CONTEXT/USER/ASSISTANT/TOOL/SUBTOOL tags); a run_code tool step nests 5 memory_read_scene sub-tool calls (SUBTOOL tags), with a detail panel for the selected step on the right">
</p>

## Layered Memory (L0–L3)

<p align="center">
  <img src="./assets/img/Layers.png" width="100%"
       alt="Four memory layers refining from top-left to bottom-right: L0 raw conversation (chat bubbles) → L1 atomic memories (glowing fact particles) → L2 scene blocks (glass document slabs) → L3 core persona (radiant crystal core); stages connected by LLM extract/consolidate/distill light beams, shrinking width shows progressive refinement">
</p>

## Per-Session Memory Modes

<p align="center">
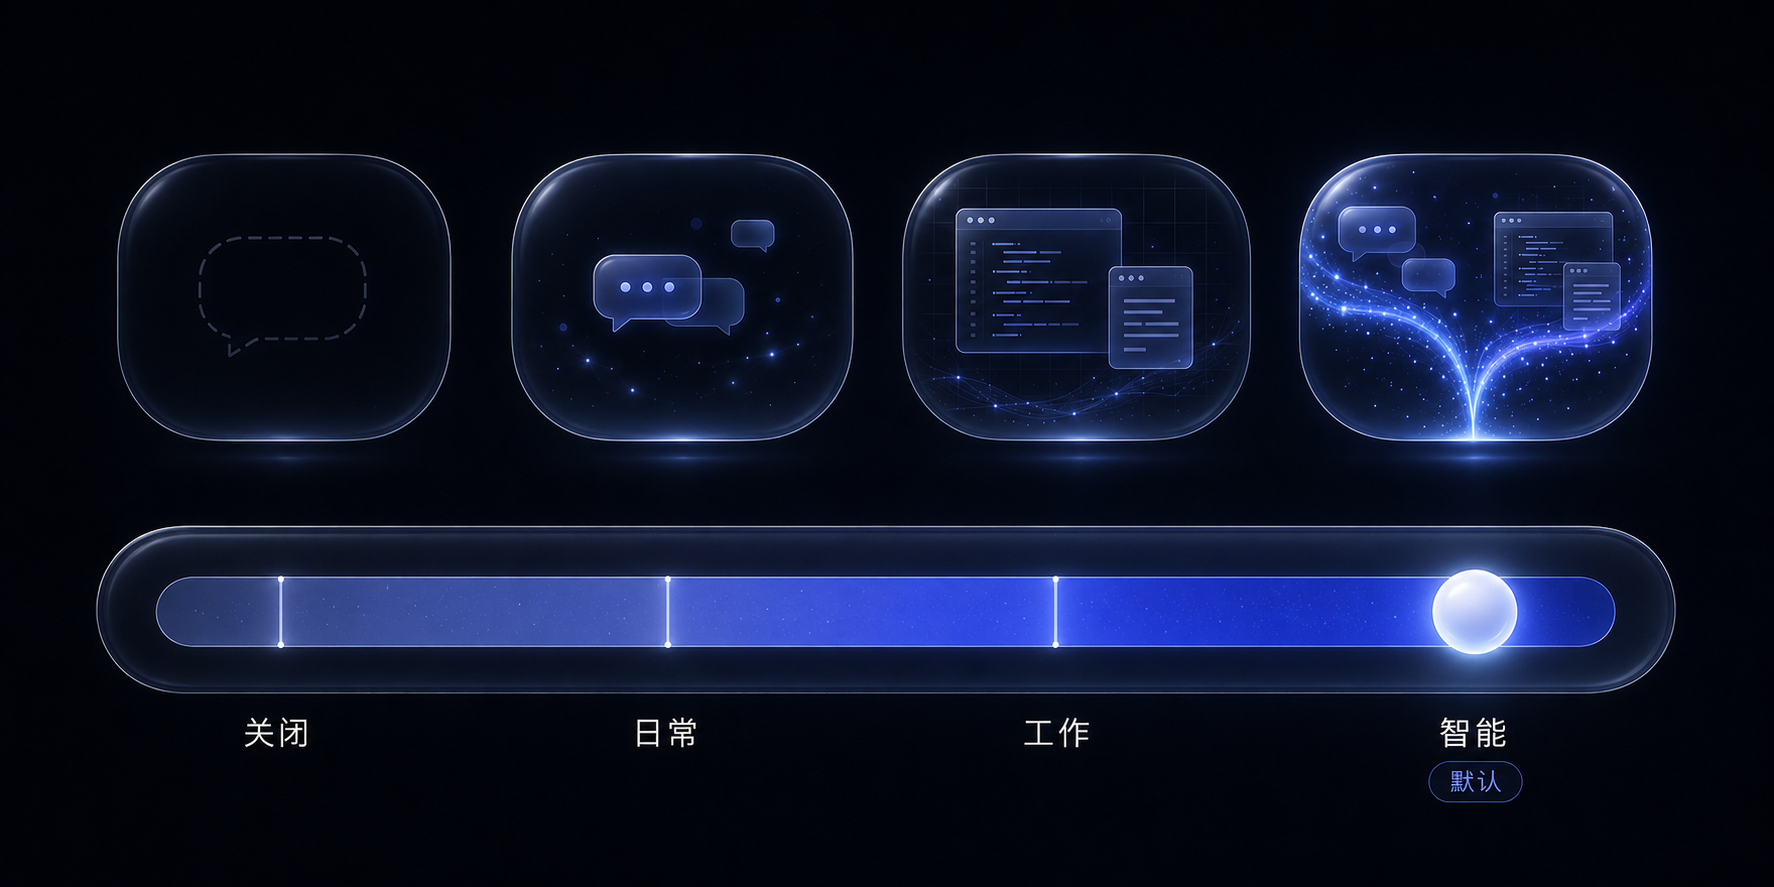
  <img src="./assets/img/Modes.png" width="100%"
       alt="Per-session memory modes: a glass capsule track with four stops (日常 · 工作 · 智能 · 关闭), the glowing orb resting on 智能 (default); a vignette above each — personal chat bubbles for 日常, code/document panes for 工作, two streams merging brightest for 智能, a dim dashed ghost bubble for 关闭">
</p>

- **Control**: the pill next to the mode selector in the input bar (`Memory · Auto`);
  clicking opens a macOS-style sliding picker above — release to snap to the nearest
  mode; adapts to light/dark themes;
- The lower half of the popover is a **per-session info area**: recall hits
  (hit/searched turns plus cumulative items), batching progress (this session's
  slice x/effective threshold; the off mode shows parked slices instead), memories
  produced for this session, and session message count — plus status lines for
  anomalies (storage degraded / vector search unavailable) and a global summary
  (pending distill count, last distill time). Data comes from the
  `dsh-memory/session-stats` endpoint (in-memory registries + an indexed COUNT,
  zero file I/O), adaptively polled while open (2s busy / 5s idle) and stopped on
  close;
- Each session's choice is persisted by sessionId to `session-modes.json`, surviving
  restarts/session restore; stacks with the global switches (global is the master gate);
  L2/L3 are fully family-isolated — content never leaks across families.
- **Write-only sessions (#38)**: a three-state "injection" switch inside the popover
  (follow global / on / off) — set to "off" for a **write-only session**: capture and
  distillation continue as usual (conversation still settles into L0→L1→L2/L3), but
  nothing is injected into this session (recall injection, the persona/navigation
  stable section and the tools guide all stop; `memory_search` and the other read
  tools return a write-only notice). The pill face changes to `Memory · Write-only`;
  the override persists per session, and switching back to "follow global" clears it
  to the settings-page recall toggle. Ideal for debug/eval/sensitive sessions that
  should absorb without interference. Orthogonal to the off mode: off remains full
  stealth (capture off too), while write-only keeps the "in" and gates the "out".

## UI Preview

<p align="center">
  <img src="./assets/img/ui-dark.jpg" width="49.5%"
       alt="Settings memory browser overview in dark theme: status card (plugin version, capture/distill/recall switch states, FTS and vector capabilities, L1 memory count, distillation model) and stat tiles, glassy controls with a cold-blue accent">
  <img src="./assets/img/ui-light.jpg" width="49.5%"
       alt="The same settings memory browser overview in light theme: identical layout and information on light card backgrounds with the same accent family, theme switch without reload">
</p>

## Measured Comparison (DSH-MemBench: Automated Benchmark)

Screenshots show what the plugin looks like — this section answers "**what does enabling it actually buy you?**" with measured numbers from an **automated benchmark** ([`bench/`](./bench/), one command to reproduce). Method: the same scenario bank with verbatim-identical inputs runs in **Group A (memory on)** with 3 merged repetitions and **Group B (memory off)** with 1 repetition (a memory-off long task burns multiples of the tokens per scenario — a cost guardrail); the dialog track now runs Group A only (memory-off probes in independent sessions cannot succeed, so the control carries no information — retired). Dialog-track environment: DeepSeek official `deepseek-v4-flash`, plugin 0.8.5 (judge same-source as tested; every answer archived for manual audit), Windows; taxonomy adapted from [LongMemEval](https://github.com/xiaowu0162/longmemeval) / [LoCoMo](https://snap-research.github.io/locomo/) / [AMB](https://github.com/vectorize-io/agent-memory-benchmark), with the extended probe types and lifecycle track informed by [MemoryAgentBench](https://arxiv.org/abs/2507.05257) / [GoodAI LTM](https://github.com/GoodAI/goodai-ltm-benchmark) / BEAM.

> The dialog track below is the **fresh 0.8.5 baseline** (fixed plugin + corrected judging criteria); the workflow-track numbers remain the archived 0.8.3 run (the bank has since grown to 8 scenarios with a prospective-memory addition — re-run pending).

### Dialog track (20 scenarios × 10 probe types × 3 reps = 420 questions): does it remember correctly

> 0.8.5 baseline (Group A data; the dialog-track B arm is retired — Group A only).

<p align="center">
  <img src="./assets/readme/bench-dialog.svg" width="100%"
       alt="DSH-MemBench dialog track accuracy chart (Group A, memory on): overall accuracy 95.2% (400/420); six core probe types, 60 questions each — extraction 58/60, multi-hop 60/60, temporal 56/60, updates 55/60, scene recall 52/60, abstention 60/60 with 0 fabricated; four extended probe types, 15 each — accretive completion 15/15, update chains 15/15, event ordering 14/15, paraphrase 15/15">
</p>

**Dual-channel recall** (Group A): passive injection hit rate **78.1%** (the answer's key points appear in the recall injection, 281/360); most of the rest the model recovered by **actively calling the memory tools** — 106 questions with active queries, **75 rescued by tools**. The end-to-end 95.2% is the composite of both channels plus model utilization. With the memory store accumulating across scenarios for the whole run, 295 probe injections carried other scenarios' memories (honestly counted) — yet accuracy actually *rose* from 92.8% (early, small store) to 97.7% (late, largest store), and offline flooding with 600 extra synthetic records moved retrieval recall@5 by only −2.8pp: interference resistance under a growing store, measured.

**Layered weaknesses**: offline retrieval metrics (recall@5, controlled replay) total 73.3%, with event ordering at 0% and scene recall at 50% — end-to-end still 93%+ thanks to model robustness over adjacent injected memories. **Efficiency triangle** (the cost of memory): injections add no latency (injected turns respond 210ms *faster* on average), recall text is ~10.3% of per-turn input, and the whole distillation pipeline costs ≈2727 input / 240 output tokens per captured message (1172 calls, 0 failures).

### Workflow track (archived 0.8.3 · 7-scenario edition · Group A ×3 / Group B ×1, real tool sandbox): does it do it right, and cheaper

<p align="center">
  <img src="./assets/readme/bench-workflow.svg" width="100%"
       alt="DSH-MemBench workflow track, Group A vs Group B: probe-phase completion A 59/69 (85.5%) vs B 10/23 (43.5%); cost comparison (Group B as the full-bar baseline, per-scenario means) — steps 24.3 vs 41.4 (B +70%), tool calls 37.7 vs 62.1 (B +65%), input tokens 266k vs 1.81M (B 6.8×); style-convention scenario probes A 12/12 vs B 0/4; long-task input tokens per scenario A 266k vs B 1.81M">
</p>

**Probe-phase completion 85.5% vs 43.5% (+42pp)**: both groups have live context during teach/change phases — the probe phase (continuation task in a fresh session) is the pure memory window. Group A scored a perfect 12/12 on all three new probe archetypes (workflow knowledge update / twin-runbook disambiguation / style-convention continuity), consistent across all three reps; Group B scored **0/4** on style-convention probes (naming/structure/thousands-separator/footer conventions exist only in memory — they cannot be explored out of the sandbox), while on the workflow-update scenario it can reverse-engineer the procedure by reading the script (discrimination limited by sandbox affordances, honestly noted).

**Long-task cost: Group B burns 6.8× Group A's input tokens per scenario** (1.81M vs 266k) — without memory the agent advances by re-exploring, and under a high reasoning effort it even builds its own projects to probe what a one-line script convention would have done; output tokens 3× (46.2k vs 15.4k), steps +70%. This is memory's core value: **what it saves is not task difficulty, but pointless round-trips and re-exploration**.

### Methodology & reproduction

```bash
node bench/harness/run.mjs --arm A --repeats 3 --provider deepseek-official --model deepseek-v4-flash   # dialog track (Group A only)
node bench/harness/run.mjs --track workflow --arm AB --repeats 3 ...                                  # workflow track (A/B arms in parallel)
node bench/harness/run.mjs --track lifecycle --arm A ...                                              # lifecycle track (gating/off/rebuild/forget)
node bench/harness/report.mjs --latest [dialog|workflow]                                               # aggregate report
node bench/harness/retrieval-metrics.mjs <runDir> --flood 200,600                                     # retrieval metrics + flooding curve
```

- Scoring: programmatic `contains-all` plus an LLM judge against key points (every answer and verdict is preserved in `result.json` for human audit); for stale-bearing probes (updates/update-chains/forget) an old value only fails when stated *as the current answer*, and abstention probes allow citing real adjacent facts while denying the asked point; workflow completion is verified programmatically from produced files and their contents (four check kinds: positive / forbidden-word / must-not-exist / exists);
- Metric surface: beyond the per-type accuracy table (6 core + 4 extended types), reports automatically include **offline retrieval metrics** (recall@5 / injection precision / stale leakage), the **efficiency triangle** (injection latency differential / injection share / distillation accounting per captured message), **scale-position analysis** (accuracy & contamination vs store growth), and the lifecycle-track section (family-gating matrix / off-mode dual assertions / rebuild fidelity / forget requests);
- Live progress: running the benchmark auto-starts a local progress panel and opens the browser (`--no-panel` to disable) — per-arm scenario/phase/message-level progress, heartbeat & activity freshness (distinguishes "stuck" from "process died"), and cumulative cost as it accrues;
- Metrics come from provider-reported usage (input with cache-hit split) and session-event folding; the steady-state cache rate excludes each session's first request (0.8.5 baseline: 89.1% — memory injection does not hurt caching);
- Regression use: run before/after a plugin change and diff with `compare.mjs` (environment header check including git SHA + Group-B control-drift warning + retrieval-metric comparison);
- Limitations (stated honestly): single machine; Group A ×3 merged, Group B ×1 (cost guardrail — noisier); judge vs tested model: same model in the 0.8.5 dialog baseline, heterogeneous in the archived workflow run (glm-5.3 judging v4-flash); the scenario bank is author-built (biased toward memory-advantage scenarios — reproduce it yourself); sandbox-file affordances partially leak procedures (Group B can reverse-engineer by reading scripts — discrimination limits honestly noted); dual-tier tool audit (strict violation voids the scenario / loose heuristic flags only), with 0 violations measured on both sides.

Full reports and per-question data: [`bench/baseline/`](./bench/baseline/).

## Configuration

Override configs go into the profile's own `cordis.patch.yml` as a **top-level bare
patch entry** (direct `id:`, not wrapped in `insert:` — an insert with the same id as
the bundle layer appends and causes `duplicate loader entry id` startup failure):

```yaml
- id: dsh-memory
  name: dsh-prime-memory
  config:                    # keys replace whole lines (no deep merge); write out all keys you want to keep
    family: auto             # default mode for new sessions: auto | chat | work
    llm:                     # static distillation route (both fields set = deployment pin,
      provider: ''           # which outranks the settings-page route chain; when empty the route
      model: ''              # follows the route-chain primary row in the settings page or the default model)
```

| Field | Default | Description |
| --- | --- | --- |
| `family` | `auto` | Default memory mode for new sessions: `auto` (both families) \| `chat` (personal) \| `work` (work); switchable per session via the input-bar control |
| `dataDir` | `$DSH_HOME/memory` | Data directory |
| `capture.enabled` | `true` | L0 capture |
| `capture.stripCodeBlocks` | `true` | Strip code blocks from assistant messages |
| `capture.maxMessageChars` | `4000` | Max characters per message |
| `capture.redactSecrets` | `true` | Payload redaction: 8 secret classes (PEM/Bearer/JWT/Cookie/vendor API keys/emails/long numbers/high-entropy IDs) become `[REDACTED:<KIND>]` placeholders at capture time — covers L0, distill input and manual writes; `false` restores plaintext (irreversible once enabled) |
| `trace.enabled` | `true` | Structured trace: recall/distill events as daily JSONL under `<dataDir>/trace/`; switch sources in the Log tab |
| `trace.retentionDays` | `14` | Trace retention in days (`0` = forever) |
| `trace.captureContent` | `false` | `true` stores recall query text (default: length + sha256 only) |
| `extract.enabled` | `true` | L1 extraction |
| `extract.minMessages` | `6` | Steady-state trigger threshold: run L1 extraction once a session accumulates N new messages. The effective threshold ramps up 1→2→4→…→N (first turn yields memories immediately, then batches to save calls) |
| `extract.idleSeconds` | `300` | Idle flush: distill a session's pending slice after N seconds of silence (catches "user left before reaching the threshold"); `0` disables |
| `extract.backgroundMessages` | `10` | Background messages attached to extraction (fetched per session from L0 — no cross-session contamination) |
| `extract.candidatePool` | `5` | Dedup candidate pool size |
| `extract.intraBatchDedupe` | `true` | Intra-batch dedupe (same round/session): normalise + cluster by vector within the same family/type before the LLM dedup call, so one conversation's fragments are not merged into a single long memory (cuts count and runtime only, not the per-inference peak) |
| `l2.enabled` | `true` | L2 scene consolidation |
| `l2.minNewMemories` | `5` | New-memory threshold since last L2 consolidation |
| `l2.maxScenes` | `12` | Scene block count cap |
| `l2.sceneContextLimit` | `3` | Max similar-scene full texts attached to the L2 prompt |
| `l3.enabled` | `true` | L3 persona distillation |
| `l3.interval` | `20` | L3 distillation interval (new-memory count) |
| `recall.enabled` | `true` | Auto recall |
| `recall.maxResults` | `5` | Max L1 records injected before each new user message |
| `recall.maxCharsPerMemory` | `500` | Per-memory character cap for injected recall (overlong lines truncated with a hint to use the memory tools for the full text); `0` disables |
| `recall.maxTotalRecallChars` | `2000` | Total character cap per injected recall batch (lowest-ranked tail dropped first); `0` disables |
| `recall.timeoutMs` | `5000` | Overall recall budget (ms): a timed-out recall skips that turn without blocking the chat; `0` disables |
| `recall.includePersona` | `true` | Inject persona context into the system prompt (`<user-persona>`, stable zone) |
| `recall.includeSceneNav` | `true` | Inject scene navigation into the system prompt (`<scene-navigation>`, stable zone) |
| `recall.strategy` | `hybrid` | Retrieval strategy: `keyword` / `embedding` / `hybrid` |
| `recall.scoreThreshold` | `0.3` | Recall score threshold (below is not injected; applies to keyword/embedding only, not pre-fusion hybrid; tool path unfiltered) |
| `recall.decayHalfLifeDays` | `30` | Freshness-decay half-life for recall ranking (days, 0=off): ranking applies `relevance × max(0.5, 0.5^(days since last update / half-life))` — among similarly relevant candidates the fresh one wins (slots rotate), and an old memory loses at most half its ranking score (floor keeps long-lived facts afloat) |
| `embedding.enabled` | `false` | Vector retrieval switch; off = pure FTS |
| `embedding.baseUrl` | empty | OpenAI-compatible /embeddings endpoint (e.g. `https://api.siliconflow.cn/v1`) |
| `embedding.apiKey` | empty | API key |
| `embedding.model` | empty | embedding model name |
| `embedding.dimensions` | `0` | Vector dimensions (required when enabled; must match model output) |
| `embedding.maxInputChars` | `5000` | Max characters per text (overlong inputs truncated) |
| `embedding.maxInputTokens` | `0` | Per-text **token** budget for local embedding: `0` (default) = min(model window, hard cap 1536); >0 = explicit, clamped with a warn above the cap. Not the same guard as the row above — the character cap only bounds the remote tier and IPC size, while local crash/memory limits must be in tokens (#22) |
| `embedding.respawnOnCrash` | `true` | Whether the local-embedding child **self-heals (bounded)** after being hard-killed (#22): default on — re-fork + re-warm ≤2× per 60s window, multi-item batches resume once from the live checkpoint (the head vectors lost with the crashed child are recovered by background backfill); off returns to the old behavior (one crash stalls until host restart / source switch). Intentionally reverses the 0.26.25 "no self-heal" note. Three-layer defense = guardrail(1536) / peak-reduction(memPattern) / self-heal(respawn). |
| `embedding.timeoutMs` | `10000` | Per-call embedding timeout (ms) |
| `embedding.allowLocalModels` | `true` | Allow the local embedding tier (deployment ceiling; when off, no model downloads and no local tier in settings) |
| `embedding.mirror` | `https://hf-mirror.com` | Download mirror root for local models (can be changed back to `https://huggingface.co`) |
| `embedding.proxy` | `''` | Three-state download proxy: `''` (default) = auto-detect proxy env vars (`HTTPS_PROXY`/`ALL_PROXY` etc., honoring `NO_PROXY`); `none` = disable, always direct; any other value = proxy URL (e.g. `http://127.0.0.1:7890`). Direct connections to the mirror are intermittently unreachable on some networks (connect timeouts and poisoned bytes have both been observed) — keep the default auto-detection on machines with a proxy |
| `llm.provider/model` | empty | Static distillation route (deployment pin): when **both** fields are set the route is locked, outranking the settings-page runtime route chain and the default model (deployments can force distillation onto a specific route); when empty the route follows "settings-page route-chain primary → default model". At runtime, configure the primary route and fallback chain in the **route-chain editor** under Settings → Memory → Overview → distillation parameters (pick from **configured providers**, including custom ones added in dsh Settings → Models; the primary row may stay empty to follow the default model) — a non-empty chain takes over this static config wholesale, effective immediately with no restart |
| `llm.fallbacks` | `[]` | Distillation fallback chain: an ordered list of backup routes tried one by one when the primary route fails (error / cut-off / network error / **empty output**); each entry is `{provider, model, reasoningEffort?}` (a non-empty effort overrides the global `llm.reasoningEffort`, still clamped by model capability); entries identical to the primary route are skipped; **each route gets the full `timeoutMs`**; when all routes fail, the existing per-session backoff takes over. Empty list (default) = single-route behavior unchanged (see [Distillation fallback chain & slow-TTFT models](#distillation-fallback-chain--slow-ttft-models) below); a non-empty settings-page runtime chain (`distillChain`) takes over **both** the primary route and the fallback chain (a single-row chain = explicitly no fallbacks), empty = follow this config |
| `llm.layerRoutes` | `{}` | **Per-layer distillation routing** (#34): keys `l1`/`l2`/`l3`, each holding a **complete chain** (entries like `llm.fallbacks`, **head row must have both provider+model explicitly**). A non-empty chain **fully replaces** that layer's resolution (its primary and fallbacks all come from the layer chain; the global chain no longer participates); empty/missing = the layer follows the global chain. `l1` covers both extraction and dedup call sites. Layers can also be edited at runtime in the segmented panel under distillation parameters on the settings page (takes priority over this static config); a deployment pin does not disable static layer chains (same deployer-owned config as the fallback-chain precedent). Orthogonal to and composable with the fallback chain — one complete chain per layer (ADR-0005) |
| `llm.maxTokens` | `65536` | Fallback output cap for non-layered calls. Each distillation stage has its own budget (extraction 16k / dedup 8k / L2 32k / L3 16k; auto ×4 when the reasoning effort is high/xhigh/max, so thinking can't starve the text budget); the per-layer budgets are runtime-adjustable in Settings → Memory → Overview → distillation parameters (empty/0 = built-in defaults) |
| `llm.reasoningEffort` | empty | Distillation reasoning effort: empty = **auto** (resolved from model capability: the model's default tier, else `high`); an explicit value (`off`/`none`/`minimal`/`low`/`medium`/`high`/`xhigh`/`max`) is only sent when the model declares support — effort vocabularies differ across providers (deepseek accepts `off`, OpenAI-style APIs use `none`, models that declare no tiers get nothing), and unsupported tiers degrade to not-sending with a one-time warning; output budgets auto-×4 at high/xhigh/max. At runtime, override the effort **per route** in the settings-page route-chain editor (per-row dropdown; the tier list follows each model's declared capability live, defaulting to this value) |
| `llm.temperature` | `0.3` | Distillation temperature |
| `llm.maxInputChars` | `700000` | Input character budget per distillation call (over-budget L1 inputs are chunked automatically); runtime-adjustable in Settings → distillation parameters → input budget (empty/0 = follow this value) |
| `llm.timeoutMs` | `120000` | Per-call distillation timeout (ms) |
| `tokenCost.retentionDays` | `365` | Retention (days) for distillation cost details (the `token_cost` table); rows older than this are rolled away on write. `0` = keep forever. Also the upper bound of the cost dashboard's "last N days" window |
| `tools` | `true` | Whether to register model-callable memory tools |
| `benchControl` | `false` | Register the in-process bench control service (rebuild trigger / session-mode setting / distillation usage snapshot — used by the benchmark's lifecycle track). Off by default — zero surface in production deployments; do not enable casually |
| `scope` | `global` | **Storage scope** (visibility range): `global` (default) = visible across workspaces; `workspace` = isolate the **`work` family** per workspace. **Orthogonal** to `family` (content type) — the two axes answer different questions, and all four quadrants exist (`chat×global` / `chat×workspace` / `work×global` / `work×workspace`). The `chat` family stays global by default: personal memories are meant to cross projects. **With the default `global`, behavior is byte-identical to before this setting existed** — existing single-root data is all graded `global`, and migration only labels ownership, never moves or deletes ([ADR-0008](./docs/adr/0008-storage-scope-vs-family.md) / [ADR-0009](./docs/adr/0009-workspace-identity-source.md)). When no workspace can be resolved, it falls back to `global` (no throw, no startup block) |
| `conflictFreeze.enabled` | `false` | Master switch for **conflict freeze**. When on, the dedup action vocabulary gains `conflict`: if the model judges that "both sides look right and it cannot tell", it **no longer auto-`update`s or `merge`s** — the pair is **parked** in a pending queue instead. The new memory is still stored, and **neither side is rewritten**; a human adjudicates via the `memory_resolve_conflict` tool. While off, the dedup prompt is **byte-identical** to before the feature existed (zero drift). Off by default: freezing spends human attention, so it must not be on by default ([ADR-0010](./docs/adr/0010-conflict-freeze-default-off-and-timeout.md)) |
| `conflictFreeze.maxPending` | `100` | Pending-queue cap. Once the number of unresolved pairs reaches it, new conflicts are **no longer parked** and are settled on the spot using the LLM's winner/loser (the pair is **still written to the queue** for the audit trail, with `resolution` = `auto` to distinguish it from a human verdict). The semantics are "**stop taking new ones**", not "quietly delete old ones" — that is what makes the bound structural rather than a promise |
| `conflictFreeze.timeoutDays` | `30` | Timeout fallback (days): pairs left unresolved longer than this are settled automatically at the start of the **next distillation run** (again recorded as `resolution=auto`). `0` = **no** timeout fallback (explicitly off, not "everything expires immediately"). Without a safety valve, "two contradictory memories recalled side by side forever" stays in the database permanently |

### Distillation fallback chain & slow-TTFT models

Free/slow tiers of some inference providers have **first-token latencies (TTFT) upwards of 20 seconds**, while some upstream gateways cut a silent connection at ~20s — distillation calls then fail at a fixed ~20s (`llm aborted`) long before the plugin's 120s timeout could ever matter (the scenario measured in [#31](https://github.com/drscrewdriver/dsh-prime-memory/issues/31)). Three mitigations, pick as needed:

1. **Switch route** (most direct): change the primary route live in the route-chain editor under Settings → Memory → Overview → distillation parameters (or move a fast route to the head of the chain), or pin `llm.provider`/`llm.model` statically.
2. **Fallback chain** (automatic demotion): when the primary route fails, backup routes are tried in order with no manual intervention:

   ```yaml
   llm:
     provider: opencode-go          # primary route (may be left unpinned: settings-page route-chain primary / default model)
     model: ox-alpha-free
     fallbacks:                     # entry order = demotion priority; unset = single-route behavior unchanged
       - provider: opencode-go
         model: deepseek-v4-flash
         reasoningEffort: low       # optional: per-route effort override (defaults to the global value)
       - provider: deepseek-official
         model: deepseek-v4-flash
   ```

3. **Per-layer routing** (each layer on its own channel): distillation layers want different things from a model (L1 is high-frequency and wants cheap/fast/stable; L3 tolerates slow first packets but needs strong capability), so diverging layers can get their own chain — one **complete fallback chain per layer**, while unconfigured layers keep using the global chain:

   ```yaml
   llm:
     layerRoutes:                  # per-layer routing (#34); the head row must set provider+model explicitly
       l1:                         # l1 covers both extraction and dedup call sites: a cheap, fast, stable chain
         - provider: opencode-go
           model: deepseek-v4-flash
           reasoningEffort: low
         - provider: deepseek-official   # in-layer fallback: L1 failures demote only here, never onto the global chain
           model: deepseek-v4-flash
       l3:                         # L3 persona distillation: low frequency, large inputs — a strong-capability chain
         - provider: deepseek-official
           model: deepseek-v4-flash
           reasoningEffort: high
   ```

   Layers can also be edited at runtime in the **segmented panel** (global default / L1 / L2 / L3) under Settings → Memory → Overview → distillation parameters. In-layer priority: runtime layer chain > this static YAML layer chain > global default chain, falling back level by level.

   Failure = error / cut-off / network error / **empty output** (stream ends normally with 0 characters — worthless for distillation since parsing always fails, so it is treated as a route failure rather than an empty return); caller-initiated cancellation does not demote; each route gets the **full** `llm.timeoutMs` (a shared budget would give a slow-TTFT fallback route less time than its real first-packet needs, defeating the chain); token costs are recorded per attempt (failed attempts get a row too, with whatever tokens arrived before the stream broke), and successful calls are attributed to the route that actually served. The route chain can also be adjusted at runtime in the route-chain editor under Settings → Memory → Overview → distillation parameters (no config edit or restart needed); the YAML below suits deployments that want to pin the static chain.
4. **Raise the timeout**: `llm.timeoutMs` only helps when the route is genuinely slow but the gateway doesn't cut; if the gateway kills at 20s, raising the plugin timeout is futile — use the first two layers.

## Storage Layout

<p align="center">
  <img src="./assets/readme/storage.svg" width="100%"
       alt="Storage layout: dual-write architecture (append-only JSONL source of truth + memory.db retrieval engine); file forms include conversations/records/scenes/persona/state/pending/session-modes/embedding-source/model catalog/inference runtime/log and rebuild archives; three retrieval strategies keyword/embedding/hybrid (RRF k=60); a degradation chain never blocks the host">
</p>

Vectors are off by default (pure FTS). DSH's `ctx.llm` has no embeddings endpoint;
semantic retrieval is provided by a **three-state embedding source** (off / remote /
local), switchable at runtime in the settings page — see the next section.

## Semantic Retrieval (Embedding Source)

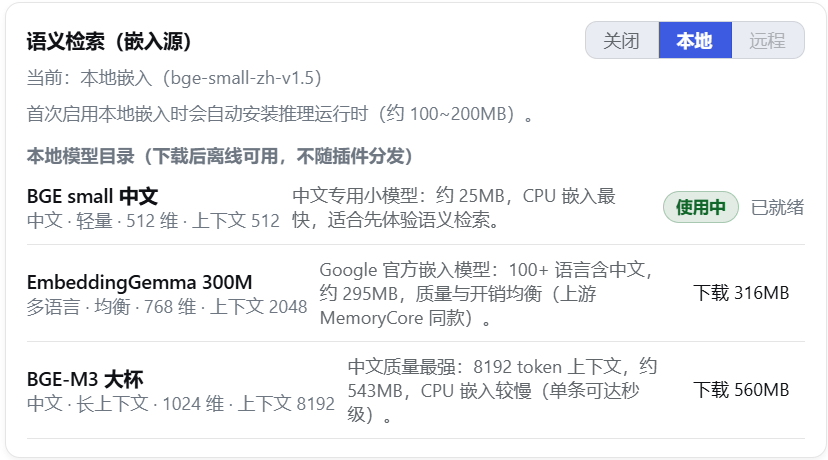
Pick the embedding source in Settings → Memory → Overview → Semantic Retrieval;
it takes effect immediately, no config edit or restart:

<p align="center">
  <img src="./assets/img/EmbeddingSource.png" width="70%"
       alt="Semantic retrieval (embedding source) panel in the settings page (light theme): a three-state selector (Off/Local/Remote, Local selected) showing the current source and the first-run runtime install hint; below it the local model catalog lists BGE small Chinese (in use/ready), EmbeddingGemma 300M (download 316MB) and BGE-M3 (download 560MB) with dims/context/size/notes and download buttons">
</p>

Three sources: **Off** (default; no vector embedding at all, pure BM25 keyword
retrieval), **Remote** (bring any OpenAI-compatible `/embeddings` service, selectable
only when the `embedding.*` quartet is configured), **Local** (pick from a built-in
model catalog, ONNX-quantized **CPU inference** — no API key, data never leaves the
machine). The local catalog is a built-in allowlist (each model pinned to a revision
with per-file sha256; arbitrary repos cannot be downloaded).

- **Download**: one click on the model card (default mirror `hf-mirror.com`, resumable
  downloads + sha256 integrity checks; a proxy is used when direct access is
  unreachable — proxy env vars like `HTTPS_PROXY`/`ALL_PROXY` are auto-detected by
  default, see `embedding.proxy`). Per-file failures auto-retry with a rotated cache
  key (`?dshmem-retry=N`, sidestepping occasionally bad CDN cache objects); hash
  mismatches restart from zero, network errors resume from the checkpoint; stored
  under `models/<id>/` in the data directory, deletable from the settings page at any time;
- **On-demand runtime**: the inference runtime (transformers.js, ~100–200MB) is
  installed only on first switch to the local tier, into `runtime/` in the data
  directory — never in the plugin's dependency tree or install directory; model
  loading and inference run on a **dedicated worker thread**, so the host event
  loop is never frozen (conversations and page interactions stay responsive while
  text is being embedded);
- **Live switching**: one click to swap sources — everything is re-embedded in the
  background (visible progress, cancellable; retrieval silently degrades to keywords
  in the meantime, conversations unaffected; a dimension change rebuilds the vector
  table at the new size); a failed switch keeps the old source, which a restart
  still uses;
- **Effective = deployment ceiling AND runtime choice**: `embedding.allowLocalModels=false`
  disables the local tier entirely; without the `embedding.*` quartet the remote tier
  is unavailable (enterprise deployments can lock this down). The choice persists in
  `embedding-source.json`.

## Logging & Troubleshooting

The dsh host prints plugin logs to the console; the plugin mirrors info and above to
`memory.log` in its data directory. The typical log path of one conversation turn:
`L0 capture` → `L0 flush` → `distillation pipeline start` → `LLM call (input/output
chars, duration)` → `L1 extraction done` → `pipeline end`; the next turn shows
`recall hit N L1 records`. Empty LLM output carries full diagnostics (finish reason /
token counts / reasoning excerpt); JSON parse failures include the first 400 characters
of the raw model output; all failure warns carry the first stack frame. The JSONL
fact source is appended per turn and relies on OS write-back (no per-line fsync);
an extreme crash (power loss) loses at most a small tail, and the index DB can be
fully re-derived from the fact source via "Rebuild memories".

## Differences from MemoryCore

- The full pipeline is embedded (no external Gateway); distillation reuses DSH's own LLM;
- L2/L3 changed from "LLM manipulates file tools" to "LLM outputs operation JSON / full documents, engineering side executes";
- Recall injection happens at `agent/pre-step` (message-side synthetic message, the official pre-step replacement semantics) plus agent-scoped `systemPrompt.context` (persona/navigation stable zone — DSH-native events/services);
- Storage/retrieval is a single-machine slimmed version of the official sqlite backend (drops multi-tenant isolation columns, TCVDB cloud backend, audit tables; tokenization uses jieba like the official one — @node-rs/jieba prebuilt binaries union CJK character bigrams: word tokens give BM25 exact-word hits while bigrams keep sub-word recall; on load failure it falls back to pure bigrams, and FTS indexes are rebuilt automatically via a tokenizer version stamp).

## Credits

The direct upstream of this repository is
[JunNanLYS/dsh-layered-memory](https://github.com/JunNanLYS/dsh-layered-memory) — the layered
distillation memory plugin for DSH. Thanks to **JunNanLYS** for open-sourcing it: this repository
rewrites the implementation layer on top of it (the first commit `0b506b8` is
"净室重写清场 — remove the old implementation and build artifacts"), while the documentation,
images and module layout are carried over from upstream. Compared with upstream, this repository
adds 12 agent-facing memory tools (high-privilege writes `memory_add` / `memory_delete` /
`memory_import`, ruminate controls `memory_ruminate`, the memory graph
`memory_search_graph` / `memory_expand_graph_node`, decision-receipt backtracking
`memory_receipts`, and conflict adjudication `memory_resolve_conflict`), the `skills/memport`
cross-tool memory transfer, and storefront screenshot declarations; the deterministic
write-plane adds three more (`memory_update` / `memory_reproject` / `memory_migrate_relation`,
see the "Deterministic graph write plane" section).

Two of those tools exist for **traceability**:

- `memory_receipts` — trace **where a memory came from**. Every L1 dedup decision leaves a
  receipt (a digest of the candidate pool it saw + the verdict), so you can ask "which run did
  this record come from, and what candidates did it see?" per record, or "what did that batch
  decide?" per run. Receipts must exist *before* the event — input snapshots cannot be
  backfilled ([ADR-0006](./docs/adr/0006-l1-decision-receipts.md)).
- `memory_resolve_conflict` — adjudicate conflict pairs parked by **conflict freeze** (see the
  `conflictFreeze.*` settings). The verdict is `winner` / `loser` / `both`: picking a side
  retires the other from retrieval, while `both` means the two records are really independent
  facts and both are kept.

The core memory capabilities (layered distillation pipeline, prompt design, and the
dual-write storage architecture) are modeled after **MemoryCore** from
[TencentCloud/TencentDB-Agent-Memory](https://github.com/TencentCloud/TencentDB-Agent-Memory).
Thanks to the original project for open-sourcing its design and implementation.

## Memory Retirement, Recovery, and Cleanup

Deletion has **two tiers**, and the tier is chosen by cost: **the reversible one is the default**, while the irreversible one must be requested explicitly and always carries an export.

| Action | Endpoint / tool | Reversible | Notes |
| --- | --- | --- | --- |
| Retire (soft delete) | `memory_delete` · `dsh-memory/records-delete` | ✅ | Keeps the main-table row, closes `valid_to`, writes a supersede marker, and drops only the FTS/vector rows. **Retires 1 record by default**; for batches pass exact `ids` rather than relying on semantic matching |
| Recover | `dsh-memory/records-restore` | — | Clears the retirement marker and rebuilds indexes, returning the record to recall |
| Physical cleanup | `dsh-memory/cleanup-retired` | ❌ | The plugin's **only irreversible** action. **Dry-run by default** (omitting `dryRun` deletes nothing); even when executed explicitly it first writes a full-library snapshot and verifies it **by content hash**, aborting with zero deletions on any mismatch |
| List snapshots | `dsh-memory/snapshots-list` | — | Lists the snapshots under `snapshots/` that have a valid manifest, with reason and record counts |
| Restore from snapshot | `dsh-memory/snapshot-restore` | — | Writes cleaned-up records back. **Dry-run by default**; accepts snapshot directory names only, never paths |

All three retirement paths — conflict verdict, dedup supersede (`update`/`merge`), manual delete — **share one primitive**, so "delete" means the same thing in all of them: recoverable.

### How the cleanup safety net is built

Physical deletion must be preceded by a snapshot that passes verification (see the table above). The way back is:

1. `dsh-memory/snapshots-list` — get the snapshot directory name (shaped like `l1-<timestamp>-<reason>`);
2. `dsh-memory/snapshot-restore` — dry-run first to read `missing` (how many records would genuinely come back, not the snapshot's total), then write with an explicit `dryRun:false`.

The restore entry point accepts **directory names only, never paths**: otherwise this RPC would incidentally gain the ability to read any directory and write its contents into the retrieval database. Restore itself is an idempotent upsert and can be re-run safely.

> **One semantic you need to know**: `cleanup-retired` only removes **already-retired** records, and the snapshot is taken **before** deletion — so every record a cleanup snapshot can bring back carries a retirement marker. By default `snapshot-restore` only writes the row back to the main table (and reports it honestly in `stillRetired`); **"back in the main table" ≠ "back in recall"**. For a genuine one-call rollback add `unretire: true`, or call `records-restore` on that batch of ids afterwards.

## Memory expiry tiers and supersede-chain lookup

A memory's "temporality" splits into **four non-substitutable axes** ([ADR-0022](./docs/adr/0022-expiry-tiering-and-validity.md)):
retirement mode (supersede marker), validity state (derived at query time), objective persistence, and the
real-world validity window (`valid_to`). The old model crammed all four into one `valid_to` column — the cost
was that perfectly legal historical memories ("a trip that ended in 2020") were **silently shadowed from the
retrieval surface** although they never retired.

| Tier | Meaning | Indexed | Auto-injected (default) | Explicit tool query |
| --- | --- | --- | --- | --- |
| `current` | open-ended, not past its window | ✅ | ✅ | ✅ |
| `historical` | point/closed-span/timeless, not retired | ✅ | ✅ | ✅ |
| `expired` | window closed **with trustworthy evidence** | ✅ | ❌ (gated, gate 2) | ✅ `include_expired` |
| `expired_suspect` | same but the window source is untrustworthy (flag, never hide) | ✅ | ✅ annotated | ✅ |
| `superseded` / `retired` | soft-deleted (restorable) | ❌ | ❌ | via supersede chain only |

Three gates:

- **Gate 1 (bugfix, ungated)**: retirement is judged by the marker alone, everywhere; the first boot after
  upgrade runs one full FTS back-fill that returns wrongly-shadowed history to the retrieval surface
  (log reports back-filled/skipped counts; vectors catch up incrementally or via the manual re-index button).
- **Gate 2 (grey flag `validity.tieringEnabled`, off by default)**: when on, passive injection drops
  `expired` and keeps `expired_suspect` with a "suspected expired" annotation; recall bubbles show
  "expired since X". A same-named runtime toggle (OR-ed with the deploy config) lives on the settings overview.
- **Gate 3 (`memory_search` parameters, all off by default = byte-identical to before)**: `include_expired`
  admits trustworthy-expired rows with `state`/`valid_from`/`valid_to`/`valid_to_source`; `as_of` replays the
  validity axis at a past moment (never reviving retired rows); `follow_supersede` walks the supersede chain
  to answer "what did this entry replace".

Legacy rows get their `dsh_validity` annotation from a low-frequency local back-fill (zero LLM; touched
records are re-projected into the graph to keep it fresh). The classifier is a single source: the six tiers
are query-time predicates, never wall-clock-driven stored state.

## Deterministic graph write plane and the correction channel

The graph is a **derived projection** of L1: nodes/edges are always recomputed from current
facts, so the single source of truth for every write is L1 itself —
**correction = edit the source + reproject, never hand-written SQL**. This plugin does not
offer, and will never offer, an entry that bypasses projection to write `graph_*` tables
directly ("zero source-less facts" invariant: every edge traces back to live L1 records via
`sourceRecordIds`).

| Action | Tool | Preconditions | Notes |
| --- | --- | --- | --- |
| Revise one memory | `memory_update` | high-privilege mode | Read old → create new (`version+1`, new id) → old row retires via the shared soft-delete confluence with a `superseded` marker (restorable) → new version enters retrieval; then both [old, new] ids are force-reprojected so graph edges follow (edges supported only by the old source get tombstoned). Not a physical delete; the JSONL fact source is append-only and never rewritten |
| Force reprojection | `memory_reproject` | Overview → Knowledge graph switch, or `graph.enabled` | Erases the "already projected at current version" receipts and re-enqueues at top priority, bypassing the permanent `projector_version` skip. Idempotent: in-flight jobs never pile up. **Manually added/imported memories that never showed up in the graph: this is the back-fill projection channel** (non-distilled writes now auto-enqueue; the tool remains the correction path for legacy rows and post-edit freshness) |
| Migrate one relation | `memory_migrate_relation` | high-privilege mode | Source-derived semantics: hard-validate that every `source_record_ids` is live and un-retired → the new relation lands through the deterministic projection branch (same (from, relation) with a new target closes the old edge) → a new L1 carrier record is written as the traceable basis (tagged `proposal_source=tool` plus a decision receipt). Old edges are not flipped back by later rejections: the reprojection batch pulls only the carrier, not sources whose text still describes the old relation |
| Non-distilled writes auto-enqueue | `memory_add` / `memory_import` | Overview → Knowledge graph switch, or `graph.enabled` | After a successful write, records join the projection queue at the same priority as distillation output (`GRAPH_PRIORITY_NEW`) — the "only distillation projects" bypass is closed |

Two boundaries worth knowing:

- **Frequent updates accumulate version rows**: retired old rows stay in the main table (the
  price of restorability); volume is governed by the existing `cleanup-retired` (dry-run +
  snapshot gate).
- **The graph vector path activates with the embedding source**: `graph_node_vec` is
  *structurally absent* when embeddings are off (not an empty table); once embeddings are on,
  projection wrap-up writes vectors for freshly landed active nodes (legacy nodes catch up
  via reprojection/rebuild).

## Roadmap

Features under planning — feedback and priorities welcome in the
[issue tracker](https://github.com/drscrewdriver/dsh-prime-memory/issues):

- [ ] **Git branch awareness**: associate memories with the current git branch; recall can filter/boost by branch (orthogonal to the existing memory modes)
- [ ] **Claude Code / Codex memory import**: one-click migration of existing memory assets (`CLAUDE.md`, Claude Code memory files, Codex `AGENTS.md`, etc.), fed into the layered distillation pipeline

## License

[MIT](LICENSE)