# web-access — model-facing web access for Pi
One extension, two tools, keyless and dependency-free (native `fetch`, no
`curl`): `web_search` runs general web search through a pluggable provider
(keyless DuckDuckGo by default; optional SearXNG or Brave), and `web_fetch`
reads a URL as text. Both are `direct` and active by default, and
read the `web-access` section of the shared `bytefly.json`.
```
pi --extension ./extensions/web-access # load just this extension
pi -e . # load the whole @gavin-hu/my-pi-agent package
pi install ./ # or install the package
```
## Tool rendering
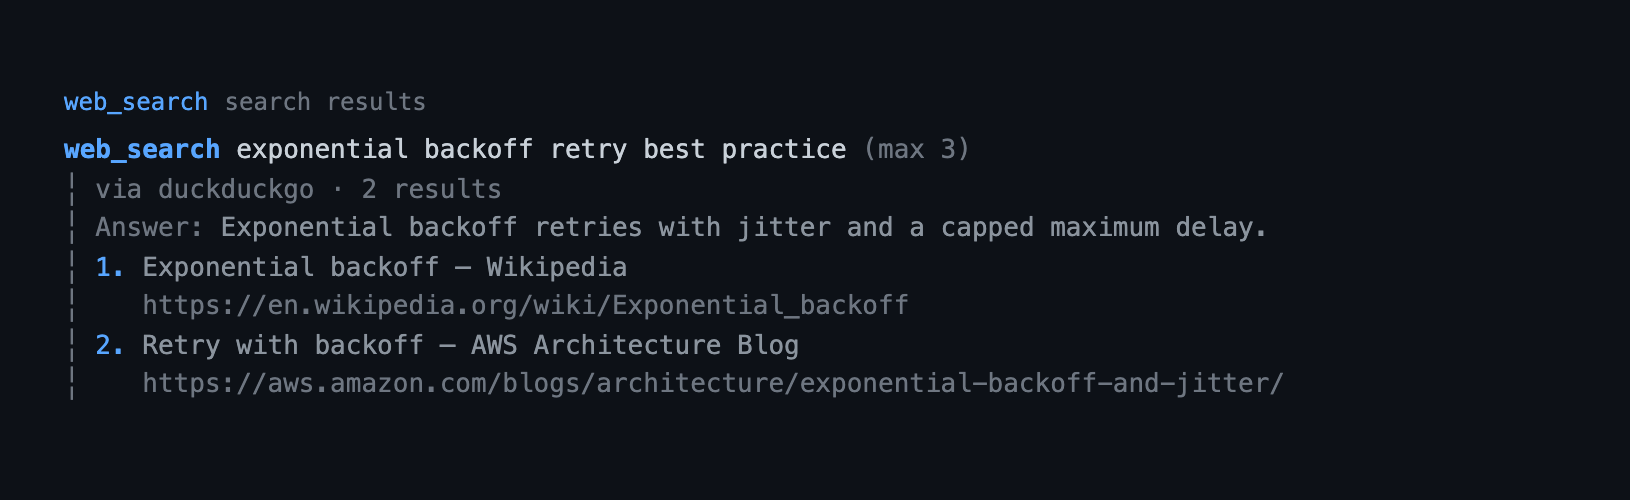
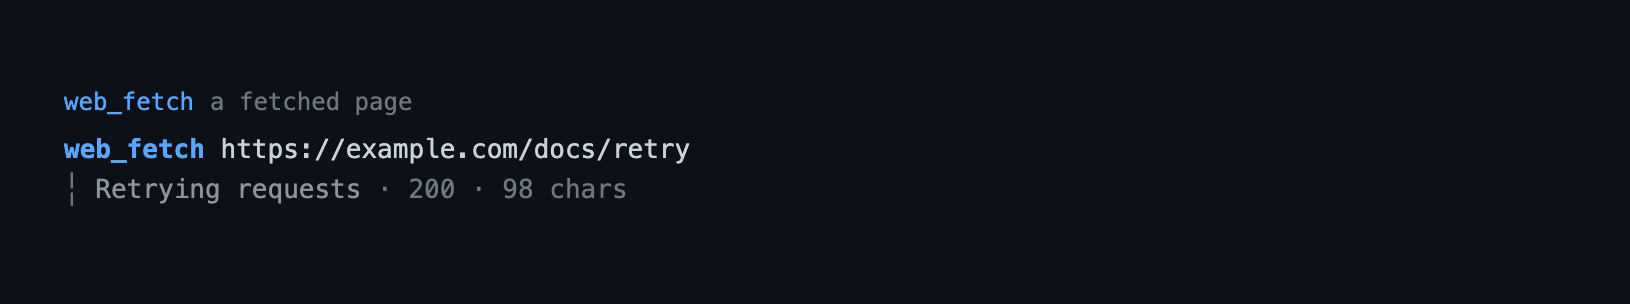
How the `web_search` and `web_fetch` calls and their results look in the transcript — the call line as a headline and the body indented under it:
 ## What it does
- Registers `web_search`, general web search through a pluggable provider:
keyless DuckDuckGo by default, or a self-hosted SearXNG instance / keyed Brave
search. Returns titles, URLs, snippets, and a direct answer when available,
always with no configuration required.
- Registers `web_fetch`, which fetches a URL (GET or POST) and
returns readable text with links kept as `[text](url)`.
- Pages long output and reports the next `startIndex` (`nextIndex` in
`structuredContent`); `find` returns matching passages instead of the whole
page, and says when the match cap hid further hits.
- Re-validates every redirect hop against private/internal addresses, and
refuses transport headers and oversized bodies.
- Optionally extracts PDFs (`unpdf`); the package loads lazily and is never
required.
- Caches fetched pages in one in-process cache per registration, so paging and
`find` do not refetch; the cache is cleared on `session_start` and
`session_shutdown`.
## Tools
| Tool | What it does |
|---|---|
| `web_search` | General web search; keyless by default, SearXNG or Brave optional. |
| `web_fetch` | Fetch a URL and return readable text, pageable and searchable. |
```
web_search({ query: "pi coding agent" })
web_fetch({ url: "https://pi.dev/" })
web_fetch({ url: "https://pi.dev/", find: ["documentation", "extensions"] })
```
### Transcript
The call line names the query or URL and states the requested limit
(`(max 8)`), so it never reads as the number of results returned. It stays one
physical line; a long URL clips in the middle so host and path both survive. The
result separates the header from its body and sanitizes untrusted web text
(answers, titles, fetched titles and errors) to one line before it reaches the
terminal. A search result labels its answer and lists one URL per result;
expanding reveals snippets and the full result list. While a request is in
flight it draws a railed `Searching… 8s` or `Fetching example.com… 3s` line, and
a finished call appends its duration. A failed page or a host-rejected call
renders one sanitized `Error:` line in the error role.
```
web_search "pi coding agent" (max 8)
via searxng · 8 results · 2.1s
Answer: Pi is a coding agent harness …
1. Pi — a coding agent harness
https://pi.dev/
2. GitHub - earendil-works/pi
https://github.com/earendil-works/pi
+3 more (ctrl+o to expand)
```
```
web_fetch https://pi.dev/
Pi — a coding-agent component · 200 · 12k chars (cached) · 3.4s
```
A redirect adds its target (`· → https://pi.dev/docs`), so the transcript shows
which URL supplied the text.
## Configuration
Merged from the `web-access` section of the global `bytefly.json` and the
project `/.pi/bytefly.json` (project wins). Missing or malformed documents
and unknown keys are ignored.
```jsonc
// bytefly.json → "web-access"
{
"search": {
"provider": "auto", // "auto" | "duckduckgo" | "searxng" | "brave"
"endpoint": "http://localhost:8080", // SearXNG base URL; "" means SearXNG is unavailable
"language": "auto", // SearXNG: "auto" (zh-CN for Han, else en) | language code
"safeSearch": 0, // SearXNG: 0 off, 1 moderate, 2 strict
"categories": "general", // SearXNG categories
"apiKeyEnv": "", // env var naming a key (Brave, or an auth proxy)
"apiKey": "", // literal fallback key
"maxResults": 8, // 1–20
"timeoutMs": 15000, // 1000–120000
"maxBytes": 5000000, // response size cap
"minIntervalMs": 500, // spacing between requests
"maxOutputChars": 12000, // model-facing budget
"userAgent": "my-pi-agent/0.1 (+https://github.com/gavin-hu/my-pi-agent)"
},
"fetch": {
"timeoutMs": 20000, // 1000–120000
"maxBytes": 5000000, // response size cap
"maxOutputChars": 20000, // default/ceiling for maxChars
"userAgent": "my-pi-agent/0.1 (+https://github.com/gavin-hu/my-pi-agent)",
"acceptLanguage": "zh-CN,zh;q=0.9,en;q=0.8",
"allowPrivateHosts": false, // true disables the SSRF guard
"maxRedirects": 5, // 0–10 hops, each re-validated
"maxBodyChars": 100000, // request body cap (POST)
"pdfEnabled": true, // extract PDFs (needs unpdf)
"cacheEnabled": true,
"cacheTtlMs": 300000, // 0 = never expire
"cacheMaxEntries": 8,
"cacheMaxBytes": 8000000
}
}
```
`search.language`, `safeSearch`, and `categories` apply to the SearXNG provider
only. `apiKeyEnv` names an environment variable holding a key (preferred);
`apiKey` is a literal fallback. For SearXNG behind an auth proxy the key is sent
as `Authorization: Bearer `; for Brave it is sent as
`X-Subscription-Token`.
## Security
- Fetched page text and search snippets are untrusted and may contain
prompt-injection content; both tools return it as-is.
- **Transcript sanitization.** The web strings the transcript draws (search
answers and titles, fetched page titles and errors, URLs and `find` terms) are
collapsed to one sanitized line before a theme colour is applied, so control
characters from a page cannot restyle or corrupt the terminal.
- `web_fetch` requires http(s), rejects obvious internal hostnames, and refuses
any host that resolves to a loopback, RFC1918, link-local, unique-local,
multicast, or metadata address. `allowPrivateHosts: true` opts out.
- Redirects are followed manually and every hop is re-validated, so a public URL
cannot redirect into a private address.
- Transport headers (`Host`, `Content-Length`, `Connection`, `Transfer-Encoding`,
and similar) are refused, and request bodies are capped.
## `web_search`
`web_search` runs through one pluggable provider, selected by `search.provider`
(`"auto"` by default).
| Provider | Transport | Configuration | Returns |
|---|---|---|---|
| `duckduckgo` | Instant Answer JSON API, keyless | none | a direct answer and related topics — **not** a general result list |
| `searxng` | SearXNG JSON API (`format=json`) | `search.endpoint` | general results (title/URL/snippet) and answers |
| `brave` | Brave Search API, keyed | `search.apiKeyEnv` / `search.apiKey` | general results |
Under `"auto"`, the first configured non-default provider wins — SearXNG when
`endpoint` is set, else Brave when a key is set — and otherwise the keyless
DuckDuckGo provider is used, so `web_search` always works with no configuration.
There is **no failover**: exactly one provider runs, and a failure is reported.
Honest limitation of the keyless default: DuckDuckGo's Instant Answer API returns
answers and related topics, not a paginated list of web results. For full result
lists, configure SearXNG or Brave.
The SearXNG instance must have the **JSON API enabled** (`format=json` in its
`settings.yml`); most public instances disable it, so a self-hosted instance is
recommended. If the response is not JSON, the error says so.
| Parameter | Type | Notes |
|---|---|---|
| `query` | string | 1–400 chars, required, any language |
| `maxResults` | integer | 1–20, capped by the configured maximum (default 8) |
```
web_search({ query: "pi coding agent" })
web_search({ query: "广州 早茶 文化" }) // Han text → SearXNG language zh-CN
web_search({ query: "python list comprehension", maxResults: 3 })
```
## `web_fetch`
GETs (or POSTs) an http(s) URL and returns readable text. HTML becomes
plain text with links kept as `[text](url)`; JSON/text/XML is returned as-is;
PDFs are text-extracted when the optional `unpdf` package is installed; other
binary content is reported by type and size. Redirects are followed manually and
**every hop is re-validated**, so a public URL cannot redirect into a private
address. Loopback, private, link-local, and cloud-metadata addresses are refused.
| Parameter | Type | Notes |
|---|---|---|
| `url` | string | Absolute http(s) URL, required |
| `method` | enum | `GET` (default) \| `POST`. POST is for read-style APIs |
| `headers` | object | Extra request headers (transport headers are refused) |
| `body` | string | POST body; implies `method: "POST"` unless set explicitly |
| `startIndex` | integer | Code-point offset to start from (default 0) |
| `maxChars` | integer | ≥200; capped by `maxOutputChars` |
| `find` | string[] | 1–10 strings; return matching passages instead of the page |
| `mode` | enum | `insensitive` (default) \| `exact` \| `fuzzy` |
| `contextChars` | integer | 0–2000 chars of context per match (default 200) |
| `maxMatches` | integer | 1–50 matches (default 8) |
| `refresh` | boolean | Bypass the page cache and refetch |
Long pages are paged: a truncated page names the `startIndex` to use next, inside
its own character budget, and `structuredContent` repeats it as `nextIndex`.
Fetched pages are cached for the registration, so paging and `find` do not
refetch. POST responses and requests with custom headers are never cached.
`structuredContent` is the page object, with an `error` field when the fetch
failed and `matchesTruncated` when `maxMatches` capped the match list.
```
web_fetch({ url: "https://pi.dev/" })
web_fetch({ url: "https://example.com/long-article", startIndex: 20000 })
web_fetch({ url: "https://pi.dev/", find: ["documentation", "extensions"] })
web_fetch({ url: "https://api.example/graphql", method: "POST", headers: { "Content-Type": "application/json" }, body: '{"query":"{ viewer { login } }"}' })
```
### Optional dependencies
PDF extraction needs a package that is not installed by default; it is loaded
lazily, so the extension stays dependency-free until you enable it.
| Feature | Package | Enable |
|---|---|---|
| PDF text extraction | `unpdf` | `npm i unpdf` (on by default once installed) |
When `unpdf` is missing, the PDF path falls back to a plain binary note naming
the content type and size.
## Limitations
- **SearXNG needs the JSON API enabled.** `web_search` runs keyless by default
(DuckDuckGo Instant Answer), which returns answers and related topics rather
than a general result list; configure `search.endpoint` for a self-hosted
SearXNG or `search.apiKeyEnv` for Brave to get full web results. Result quality
follows the engines the provider uses.
- **Heuristic extraction**: `web_fetch` strips scripts/styles/nav/footer and
prefers ``/``, but is not a full readability engine. PDF
extraction is optional (`unpdf`) and off unless installed.
- **The page cache is in-memory and per registration**; a page can be stale
within a session. `refresh: true` refetches, and it is cleared on
`session_start` and `session_shutdown`.
- **Untrusted content**: fetched page text may contain prompt-injection attempts;
treat it as data, not instructions.
- The SSRF guard covers every redirect hop, but DNS rebinding is a residual
risk.
## Non-goals
- `web_search` does not scrape a search-results page: each provider speaks a
JSON API (DuckDuckGo Instant Answer, SearXNG, or Brave). No keys are required
for the keyless default.
- `web_fetch` does no model call; it returns text and lets the model reason.
- PDF extraction exists only through the optional, lazily loaded `unpdf`
package, never as a required dependency.
## Pi integration
| Integration point | Value |
|---|---|
| Tools | `web_search`, `web_fetch`; `exposure: "direct"`, both `defaultActive: true` |
| Execution mode | `web_search`: `sequential`; `web_fetch`: default |
| Annotations | both `readOnlyHint: true`, `openWorldHint: true`, `destructiveHint: false` |
| Output | `outputSchema` (`WebSearchOutput` / `WebFetchOutput`) plus matching `structuredContent` |
| State | none in the session branch; one fetch page cache per registration (`web_search` keeps a per-instance throttle) |
| Lifecycle | the factory only registers (`index.ts`); `registerFetchTool` owns the page cache and clears it on `session_start` and idempotent `session_shutdown` |
## Design notes
- **Two self-contained halves.** `search/` and `fetch/` each own their
`config.ts`, `schema.ts`, `types.ts`, `format.ts`, and `tool.ts`, and do not
import each other; `index.ts` only registers. Shared text and HTML helpers
live at the top level (`text.ts`, `html.ts`, `transcript.ts`, `http.ts`).
- **Shared transport.** [`http.ts`](./http.ts) holds the fetch runner
(`HttpRunner`, `createFetchRunner`, HTTP error types), used by both halves and
injectable for tests.
- **One config file, isolated sections.** `config.ts` reads the global then
project file and validates each section with its half's normalizer; unknown
keys and malformed files are ignored.
- **Native fetch, no required dependencies.** PDF extraction loads `unpdf`
lazily and falls back to a binary note when it is absent.
- **Per-hop SSRF validation.** Redirects are followed with `redirect: "manual"`
under one shared deadline, re-resolving and re-checking each `Location`.
- **Pluggable search providers.** [`registry.ts`](./search/registry.ts) holds a
value-only provider list (`duckduckgo`, `searxng`, `brave`) and a pure
`resolveProvider`; [`search.ts`](./search/search.ts) owns selection, key
resolution, a per-instance throttle, and error mapping. A provider with no
answer and no results reports `provider: "none"`.
- **Find-in-page.** `exact` is case-sensitive, `insensitive` lowercases both
sides, and `fuzzy` scores lines by the fraction of query terms they contain
(a spaceless CJK term expands to its characters), keeping lines ≥ 50%.
Offsets line up with `startIndex` so a hit can be read with a second call.
- **Injected seams, no module state.** `registerSearchTool`/`registerFetchTool`
take deps: the search half a runner and throttle, the fetch half a
`FetchDeps` (`http`, `pdf`, `render`) plus its own page cache. Nothing
mutable is held at module scope.
- **The paging budget is explicit.** `formatPage` counts the header and the
truncation note against `maxChars`, so a paged page always carries its
`startIndex` hint inside the limit.
- **One JSON boundary per concern.** `search/json.ts` owns `requestJson` (status
check and parse error) and `collectResults` (title + http(s) URL + de-dupe), so
the three providers cannot drift on either.
- **Page cache.** [`fetch/cache.ts`](./fetch/cache.ts) is a factory
(`createPageCache`) holding an LRU/TTL map keyed by requested URL, so paging and
find are a single fetch; entries evict by count and total bytes, and one
instance belongs to one registration.
- **Transcript sanitization and reuse.** [`transcript.ts`](./transcript.ts)
holds `oneLine`, shared by both tools to collapse untrusted web text to one
sanitized, optionally clipped line; the renderers reuse
`context.lastComponent` instead of allocating each render.
## Files
| File | Purpose |
|---|---|
| `index.ts` | Register both tools |
| `config.ts` | The `web-access` section of `bytefly.json` loader (via `lib/config.ts`) |
| `http.ts` | Shared fetch runner and HTTP error types |
| `text.ts` | Shared code-point length, slice, and truncation helpers |
| `html.ts` | Shared HTML entity decoding |
| `transcript.ts` | Shared `oneLine` sanitizer for both transcript renderers |
| `search/tool.ts` | `web_search` definition, activation, rendering |
| `search/provider.ts` | Provider interface (`SearchProvider`, `ProviderContext`) |
| `search/registry.ts` | Value-only provider list, `resolveProvider`, labels |
| `search/config.ts` | Search config type, defaults, clamping, API-key resolution |
| `search/schema.ts` | Params/output schema, `resolveRequest()` |
| `search/search.ts` | Provider resolution, throttle, and outcome mapping |
| `search/providers/duckduckgo.ts` | Keyless Instant Answer JSON provider |
| `search/providers/searxng.ts` | SearXNG URL builder, response parser, and client |
| `search/providers/brave.ts` | Brave keyed JSON provider |
| `search/json.ts` | Shared provider JSON fetch (`requestJson`) and result collection |
| `search/format.ts`, `search/types.ts` | Result text and data types |
| `fetch/tool.ts` | `web_fetch` definition, activation, rendering |
| `fetch/config.ts` | Fetch config type, defaults, clamping |
| `fetch/schema.ts` | Params/output schema, `resolveRequest()` |
| `fetch/page.ts` | Fetch + redirect-following + content-type routing |
| `fetch/ssrf.ts` | URL/host validation and private-address blocking |
| `fetch/extract.ts` | HTML → title + readable text |
| `fetch/pdf.ts` | Optional PDF text extraction via lazy `unpdf` (injected via `FetchDeps`) |
| `fetch/find.ts` | Passage search (exact/insensitive/fuzzy) |
| `fetch/cache.ts` | Per-registration LRU/TTL page cache (`createPageCache`) |
| `fetch/format.ts`, `fetch/types.ts` | Result text and data types |
## Testing
`extensions/web-access/` mirrors the halves (`search/`, `fetch/`) plus top-level
`config.test.ts` and `index.test.ts`. It covers the shared runner (via injected
`fetch`), the provider registry and resolution, each provider's URL builder and
parser (DuckDuckGo, SearXNG, Brave), the orchestration pipeline and throttle,
redirect re-validation (per-hop SSRF with literal IPs), method/header/body
validation, the nested config merge and section isolation, extraction,
formatting/paging through the tool (including a regression test that a truncated
page keeps its `startIndex` hint), find and its cap notice, the per-registration
cache, the SSRF guard, the injected PDF dependency, and both tools'
registration/execution. Tests inject the runner, throttle, and PDF extractor
through the tools' dependencies, so no network or PDF library is needed; the
runtime smoke test only asserts registration.